Google Introduces Gemini 3.8 Live Avatar: A Digital Human for Real-Time Conversation
It listens to voice, processes live visual scenes, and responds with synchronized speech and dynamic avatars; asynchronous tool calling keeps reception, touring, and service dialogues flowing.
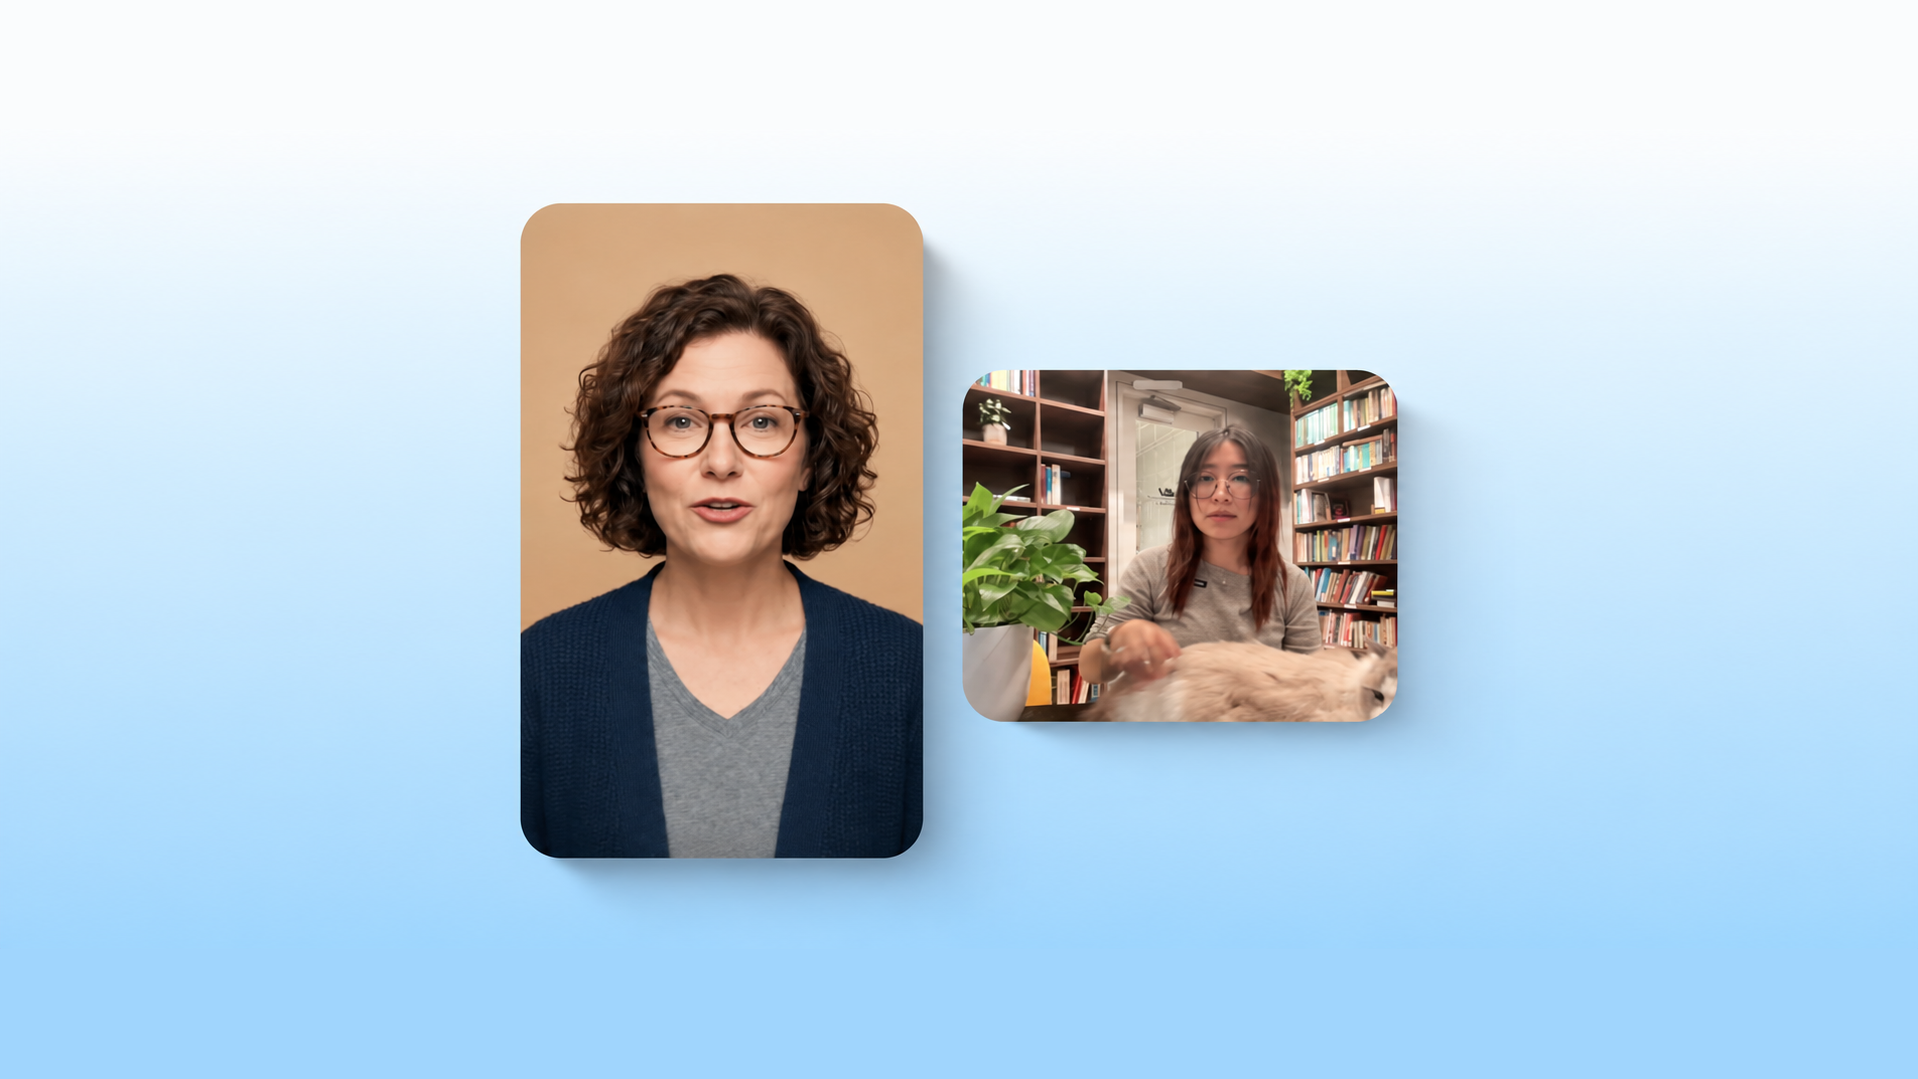
Google has released Gemini 3.8 Live Avatar, introducing dynamic digital avatar capabilities that can see, hear, and speak during conversations. By pairing real-time voice interaction with low-latency video streaming, the avatar's voice, lip sync, and facial expressions continuously adjust to the ongoing dialogue; when queries or operational requests arise, it can also execute tool calls in the background. This provides a persistent, interactive visual presence for reception, guided tours, and customer support.
What Has Upgraded in the Core Technology
Google describes this advancement as natively combining real-time conversation with streaming video. The system ingests audio and visuals simultaneously while streaming synchronized speech and dynamic avatar imagery; lip movements, expressions, and speaking cadence shift alongside answers. The key breakthrough is keeping dynamic avatars aligned with real-time user inquiries, displayed objects, and topic shifts while sustaining a natural conversational rhythm.
Another major upgrade is asynchronous tool calling. The AI can trigger external queries or operational workflows mid-conversation and maintain active dialogue with the user while awaiting results. This transforms the front-end experience: requests such as checking room availability or retrieving order details no longer freeze the avatar in place. However, business outcomes are still returned by the enterprise's integrated backend systems, and smooth dialogue in demo videos does not replace verification of actual execution success.
Key Features
- Listening and seeing simultaneously to answer from live context. Users can speak or present objects and surroundings to the camera; the AI interprets spoken queries alongside visual cues before responding with expressive voice and video.
- Calling tools while conversing. Tool requests execute in the background, making them well-suited for connecting Q&A to workflows like reception and lookups. Actual capabilities depend on the APIs integrated and permissions granted by the enterprise.
- Maintaining avatar synchronization across languages. Google states that Live Avatar can switch between 97 languages while aligning lip movements and facial expressions with speech and maintaining video stability. This is an official capability claim; real-world performance in target languages must still be tested in specific environments.
- Using preset or custom brand avatars. Businesses can choose from a preset character library or customize dynamic avatars using high-quality reference images. Custom avatars are currently subject to enterprise allowlist requirements.
What the Four Official Demos Show
Spotting unprompted risks in view. A user holds up Kai, a ragdoll cat, in front of the camera and asks how to keep it comfortable in an office. The avatar first offers advice on cat beds and rest, then notices a pothos plant on the desk and cautions the user to move it out of the cat's reach. This demo illustrates the value of visual input: responses can incorporate environmental context beyond the direct question; it does not constitute independent validation of recognition accuracy.
Progressing dialogue and business requests simultaneously. In a hotel scenario, the virtual receptionist discusses early check-in, says the guest has received a complimentary room upgrade to Room 509 and that a digital key has been sent to the guest's phone; when the guest subsequently orders a cheeseburger, room service request prompts appear on screen. This illustrates continuous dialogue powered by asynchronous tool execution; the video itself does not demonstrate integration with real hotel systems, nor should complimentary room upgrades be assumed as default product policy.
Maintaining conversation across language switches. In a travel Japanese practice scenario, the user asks questions in English, and the avatar teaches how to ask "How much is this?" in Japanese, explaining and demonstrating in English upon hearing pronunciation slips. The video specifically demonstrates switching between English and Japanese.
Selecting character appearances. The final video showcases preset avatars with diverse appearances, voices, and expressions to help enterprises assess aesthetic styles; the demo does not illustrate the process of generating custom avatars from reference images.
Where It Fits Today
Live Avatar is now available to Gemini Enterprise customers, with developer access provided via the Gemini Live API. At present, it is best suited for short-duration reception, guided touring, and customer service scenarios requiring visual and audio feedback. Google DeepMind's model card specifies that continuous interaction supports "a few minutes" rather than hours; occasional latency spikes, timeouts, and response inaccuracies remain known limitations.
Organizations planning to deploy it in production must validate target languages, latency, tool permissions, and transactional receipts. Custom avatars require enterprise allowlisting; Google notes that generated audio and video incorporate invisible SynthID watermarks to assist in identifying AI-generated content. Watermarking provides identification markers, but practical deployment still requires verifying each business transaction's outcome.
Members can copy or download the full Markdown, and let their AI subscribe and ask.
Found this useful? Leave your email — every new explainer, the moment it's out. Unsubscribe anytime.