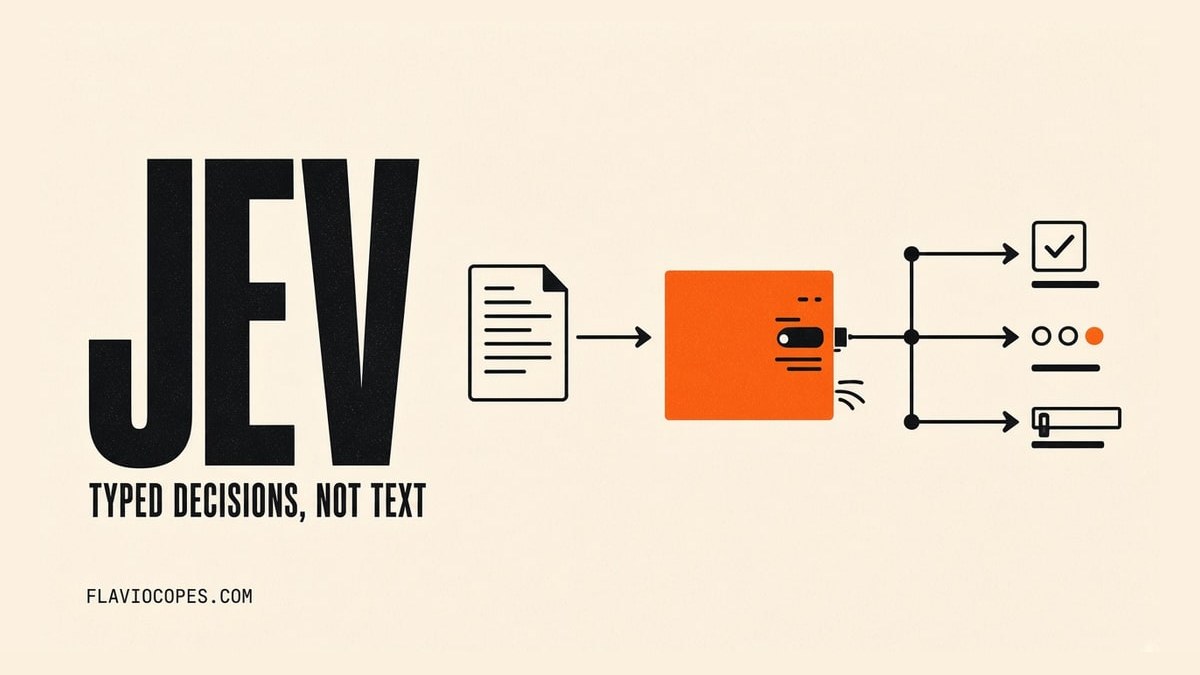
Jev Guide: How to Use an AI Model That Only Judges and Never Writes, and Where It Fits
Jev, released by TypeSafe, doesn't chat or write text—it only answers multiple-choice questions you provide and tells you how confident it is. Getting started takes just four steps, delegating installation and coding entirely to Codex or Claude Code. Through official and community real-world cases, demo videos, and our own hands-on tests, we clarify where it can be used and where it might fail.
Everyday large models—whether ChatGPT, Claude, or various coding Agents—primarily do one core job: "writing." Writing a response, writing code, or writing a summary.
TypeSafe AI's first model, Jev, takes a different route: it does not generate content. It only makes decisions among a fixed set of options.
It will not chat with you, write essays, or directly generate code. Using it is straightforward: you provide a passage of text as background material, give it several multiple-choice questions with fixed options, and within hundreds of milliseconds it hands back the answer sheet—telling you which option to pick, the probability of each option, and its degree of confidence in that judgment.
To draw an analogy using the most fundamental software concept: standard if condition checks can only evaluate rigid numbers (such as whether an order amount exceeds 100, or whether status is paid). The moment a task requires "understanding meaning"—whether a private message sounds angry, whether a comment counts as spam, or which button on screen should be clicked—static rules break down.
Jev acts as an intelligent if branch equipped with common sense. Execution flow remains governed by your code or scripts written by AI; Jev intervenes solely at the specific step where semantic understanding is needed, delivering a judgment accompanied by a calibrated confidence score.
Looking at this inside an Agent makes it clearer. Agents operate in a loop: the LLM decides what to do, tools execute, results are evaluated, and the cycle continues until the task finishes. Calling an LLM for every minor decision makes the workflow both slow and expensive. Jev takes over these granular choices: which button to click next, whether a command is dangerous, or whether a task should route to a cheap or powerful model. The parts requiring deep reasoning and writing are left to LLMs.
Key Jev Features
- Make semantic decisions among fixed options: Give it context and candidate answers, and it selects the option or options that best match the material—useful for classification, routing, and action selection.
- Return probabilities and confidence: Applications receive both the answer and how certain the model is, so they can execute automatically, observe again, or hand off to a person.
- Handle frequent small decisions: Jev does not generate long text; it concentrates compute on “which option,” making it suitable for the observe-decide-act loop inside Agents.
- Understand natural-language conditions: Sentiment, intent, risk, page elements, and task difficulty can be turned into questions even when they are hard to express as static rules.
- Integrate through coding Agents: The official skill guides Codex or Claude Code through installation, API calls, question design, and testing; developers focus on the options and acceptance criteria.

Why It's Called "System One" and Jev
TypeSafe defines this as an entirely new model category: System One models.
The name originates from Nobel laureate Daniel Kahneman's seminal book Thinking, Fast and Slow. The book divides human cognition into two systems:
- System 1 (Fast Thinking): Effortless, instinctive, and nearly instantaneous judgments based on intuition. For example, dodging an oncoming vehicle while walking, or spotting anger on someone's face at a glance.
- System 2 (Slow Thinking): Attention-demanding, deliberate, step-by-step deep reasoning. For example, calculating 17 × 24, or working through complex business logic.
Under TypeSafe's taxonomy, reasoning models handle System 2 work, while Jev specializes exclusively in System 1 work: rapid judgments delivered in hundreds of milliseconds.
As for the name Jev, it stems from the 19th-century British economist William Stanley Jevons and the "Jevons paradox": when the efficiency of steam engines drastically increased and the coal required per unit of work fell sharply, total coal consumption actually rose, because cheaper power was applied to far more use cases. TypeSafe believes intelligent judgment will follow the same pattern: when an intelligent decision costs less than a hundredth of a cent and takes only hundreds of milliseconds, software will incorporate countless judgment points where calling a model was previously unthinkable.
How to Get Started with Jev: Four Steps Delegated to AI
Installation, configuration, and API integration code can all be delegated to your coding Agent (Codex or Claude Code). You only need four steps:
- Apply for waitlist access: Request access on the official site typesafe.ai; access is typically granted the same day.
- Have AI install the TypeSafe skill: Tell Codex, "install
npx skills add typesafe-ai/skills --skill typesafe-ai". If using Claude Code, you can also have it install via the official plugin workflow: runclaude plugin marketplace add typesafe-ai/skills, followed byclaude plugin install typesafe@typesafe-ai. Either approach works. - Create an API Key: Log in to the dashboard at console.typesafe.ai and generate a key on the API Keys page.
- Start working: Add "use the TypeSafe skill" to your prompt, then state your requirements in plain language.
You only need to provide the API Key and specify what data you want to process and how you want it classified. The code generation, format integration, and testing are handled entirely by AI.

Handing It Off in One Prompt: A Real Walkthrough
To verify whether delegating everything to AI is truly seamless, we started Claude Code in an empty directory containing only a comment file comments.txt (8 example comments we wrote, not real reader comments) and entered the following complete prompt without doing anything else:
use the TypeSafe skill. Help me write a Python script triage.py: read comments from comments.txt in the current directory (one per line), use Jev to classify each into: Question, Business Inquiry, Advertisement, Praise, Complaint, Other; then determine whether this requires my personal reply; flag any classification with confidence below 0.6 as "Needs Human Review". Once written, run it against comments.txt and print results as a table. The API key is already in the environment variable TYPESAFE_API_KEY. Operate only in the current directory.
Following the TypeSafe skill guide, Claude Code wrote a 72-line triage.py using Python's standard library, ran it independently, and generated the table below:
| # | Comment | Category | Confidence | Personal Reply | Status |
|---|---|---|---|---|---|
| 1 | Does this tool have a Chinese version? I encountered an error on step 3 following your guide. | Question | 1.00 | Yes (0.89) | Auto |
| 2 | Add WeChat to claim AI side-income tutorial, earn 1000+ daily, limited spots! | Advertisement | 1.00 | No (0.05) | Auto |
| 3 | We are an AI education company and would like to invite you for a sponsored collaboration... | Business Inquiry | 1.00 | No (0.38) | Auto |
| 4 | Brilliantly written, bookmarked! | Praise | 1.00 | No (0.06) | Auto |
| 5 | Another sponsored article, boring. | Complaint | 1.00 | No (0.09) | Auto |
| 6 | Can that model you mentioned last time actually be used commercially? | Question | 1.00 | Yes (0.82) | Auto |
| 7 | Your service is truly wonderful, no one has replied to me in three days. | Complaint | 1.00 | Yes (0.58) | Auto |
| 8 | Could you publish a tutorial explaining how to build automations with Codex? | Question | 1.00 | No (0.41) | Auto |
After the run, it proactively offered suggestions (verbatim):
Three things you need to know:
- All 6 categories were classified correctly, including detecting the sarcastic complaint in item 7.
- "Needs Human Review" was not triggered once: confidence scores across all 8 items were around 1.00. The logic flagging items below 0.6 is implemented in the script; these comments were simply too distinct to trigger it.
- Two judgments on "Personal Reply" look questionable to me: item 3 is a business collaboration inquiry, given only 0.38 and marked as no reply needed; item 8 is a reader requesting a tutorial, given 0.41 and also marked as no reply needed. My recommendation: enforce business inquiries directly in code as "always reply personally" rather than delegating to the model—it's a one-line change. Let me know and I'll update it.
This process illustrates the division of labor when using Jev: deterministic business rules belong in code, ambiguous semantic interpretation goes to Jev, and glue work is handled by coding Agents.
For Those Wanting Under the Hood: What a Request Looks Like
Coding Agents will write this code for you; this breakdown simply illustrates what happens under the hood. A request consists of just two parts: state (material provided for review) and questions (questions to answer). Below is a test run on an example support ticket (an example we wrote) querying which department should handle it:
{
  "model": "jev-latest",
  "state": { "ticket": "The Bluetooth headphones I ordered yesterday (order number 20260915-8831) were charged twice, 299 yuan each time. Please refund the overcharged amount as soon as possible." },
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should `ticket` be assigned to?",
      "criteria": {
        "billing": "Charges, refunds, invoices, coupons, and other money-related issues",
        "technical": "App or website glitches, crashes, login failures, feature errors",
        "sales": "Price inquiries, bulk purchases, corporate partnerships",
        "other": "None of the above, or unclear which category it belongs to"
      }
    }
  }
}
The result returned by Jev (tested, excerpting this question):
{
  "model": "jev-1.13.0",
  "answers": {
    "department": {
      "type": "choice",
      "choice": "billing",
      "confidence": 1.0,
      "probabilities": {
        "billing": 1.0,
        "technical": 0.0,
        "sales": 0.0,
        "other": 0.0
      }
    }
  }
}
Notice two critical characteristics:
- Never answers outside provided options: Jev does not generate JSON token by token. Instead, it outputs probability distributions directly across defined choices. Consequently, answers cannot exceed options, and malformed outputs are impossible (TypeSafe calls this "0% type errors"). This does not guarantee the correct option is chosen every time—it can still make judgment errors.
- Answers all questions in one shot: All questions are evaluated in parallel during the same inference pass without cross-question interference.
Three Basic Question Types
In Jev, all judgments are mapped into three fundamental question types:
Boolean Question (Noul)
Asks whether a statement is true or false. Returns a probability value noul between 0 and 1.
Values close to 1 indicate high likelihood of "true"; values close to 0 indicate high likelihood of "false".
- Important note: A value near 0.5 signifies model uncertainty, not a "moderate degree."
- Prompting technique: Avoid asking for subjective, vague degrees; ask for clear, verifiable facts instead. Tested on an example resume we wrote:
- Asking "Is the candidate's Python skill strong?", Jev returned a probability of 0.19 (completely un-actionable);
- Reframing into two factual questions: "Does the resume mention using Python at work?", Jev returned 0.04 (definitively no); "Does the resume mention building anything with Python?", Jev returned 0.99 (because the resume mentioned writing web scrapers as a hobby). Branching business code on these two concrete facts is far more reliable than a murky 0.19.
Multiple Choice (Choice)
Selects one item from a fixed, unordered set of options. Supports up to 255 options.
Returns the top option choice, full probability distribution probabilities, and aggregate confidence.
- Important note: Build the habit of including an "Other" option. Without a fallback outlet, the model is forced to pick an ill-fitting option when presented with out-of-distribution inputs.
- Works in Chinese: In this article, the questions and options were all written in Chinese. On an example support ticket, "Your App crashes immediately upon opening the payment page, unable to place order today" was classified as a technical issue with 1.0 confidence. TypeSafe notes that English performs best; other languages work but not as strongly as English, so benchmark with your own non-English data prior to production.
Scale Scoring (Score)
Used for ordinal evaluation across an ordered scale, supporting 2 to 10 tiers.
Returns probability-weighted mean score, probabilities across tiers, and aggregate confidence.
- Anchor tiers with concrete scenarios, not bare degree adverbs.
Tested on an example bug report we wrote: "The export button does not respond when clicked in Safari, works fine in Chrome, but roughly one-third of our clients only use Safari":
- If tiers use only degree adjectives (0: Minor / 1: Moderate / 2: Severe), Jev assigned 1.94 with 0.91 confidence—seemingly decisive, yet the bug neither crashed the app nor lacked workarounds, offering no grounded basis for that certainty;
- Switching to concrete scenarios (0: Cosmetic only, functional / 1: Functionality impaired but workaround exists / 2: Blocker issue, no workaround), Jev returned a score of 1.48 with confidence dropping to 0.28, giving Tier 1 a 0.52 probability and Tier 2 a 0.48 probability. This faithfully reflects real-world nuances: manageable for Chrome users, yet a complete blocker for Safari-only clients. Framing tiers as concrete scenarios allows the model to capture ambiguity, signaling code to escalate to human review.
Confidence and "Speculative Fan-out"
Confidence: Knowing When It Is Uncertain
Standard LLMs answering multiple-choice questions often exhibit blind overconfidence even when prompted to output confidence estimates. Jev is trained using TypeSafe's RLCD (Reinforcement Learning from Calibrated Decisions), where the primary goal is probability calibration—judgments made with 90% confidence should historically reflect approximately 90% real accuracy.
TypeSafe recommends a three-tier handling logic:
- High confidence: Silent automatic execution by the system;
- Medium confidence: Request user confirmation or flag for review before execution;
- Low confidence: Skip automation and route directly to human channels.
Specific boundaries depend entirely on your operational risk profile. For instance, TypeSafe's documentation suggests intent routing can escalate to humans below 0.5, whereas irreversible, high-risk actions like "approve wire transfer" typically demand confidence thresholds above 0.9.
Tested on two example statements we wrote: an unambiguous "Check my remaining account balance" was categorized as checking balance with 1.0 confidence; an ambiguous "Please handle that money issue from last time" was assigned customer service routing at 0.88 probability, but transfer routing also received 0.12, causing aggregate confidence to fall to 0.82. Systems can intercept potential errors accordingly.
Looking at real data: classifying 200 real Chinese AI news headlines into 8 categories (New model, New feature, Research paper, Funding & business, Open source project, Tutorial & experience, Opinion & commentary, Other):
- Across 10 requests (6 concurrent), classifying all 200 items took 11.1 seconds total and consumed 42,498 input tokens, totaling only ~$0.001785 (less than 0.2 US cents) at official pricing;
- Median confidence was 0.78. 66 items had confidence ≥ 0.9, and 63 items had confidence < 0.6;
- Setting the threshold at 0.6 auto-classified 137 items, leaving 63 items escalated for human review;
- Manual verification showed high-confidence items were accurate: "Jina AI Releases jina-ocr-v1: 3.4B MoE Document Parser" ("Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs") was classified as a new model (0.96 confidence). Items with confidence below 0.6 often held genuine dual attributes: on "Claude Code v2.1.276: Fix Proxy Environment Error" ("v2.1.276"), the model hovered between product feature (0.50) and open-source tooling (0.46), yielding only 0.44 confidence.
Test Data · 200 AI News Headlines Classified into 8 Categories
Where you set the threshold determines how many items require human review
Jev provided a classification and confidence score for each item. Items meeting or exceeding the threshold use its classification directly; those below escalate to human review. Drag the threshold to see counts on both sides and inspect borderline headlines.
Auto-classified 137 items(68%)Escalated to human 63 items(32%)
Barely meeting threshold, auto-classified
- At default threshold 0.60, 137 items are auto-classified.
Just missed threshold, escalated to human
- At default threshold 0.60, 63 items escalate to human review.
Data: Xiaohu's test on 2026-09-19, jev-1.13.0, the 200 most recent headlines in our news feed (Jev classified the Chinese versions; original titles shown here), 20 per request, 6 concurrent, 11 seconds total, about $0.0018. The parentheses after each headline show Jev's top two categories and probabilities.
Tip: Ambiguous borderline items may exhibit minor numerical variance across runs (in our tests, the same borderline bug scored 1.50 and 1.44 with confidence of 0.25 and 0.34 across two runs). Always incorporate safety margins when defining confidence thresholds.
Speculative Fan-out: Querying Everything at Once
With standard LLMs, developers routinely query a first question and decide whether to call a second based on the response to conserve latency and token cost.
With Jev, the reverse holds: for independent questions regarding the same material, ask all questions in a single request. A second request is needed only when an answer dictates fetching new source material.
Tested on an example support ticket:
- Querying Jev with 4 questions simultaneously (assigned department, refund request, urgency, presence of order number) took 274 ms end-to-end and consumed 603 input tokens;
- Running 4 separate sequential requests took 268, 271, 276, and 296 ms respectively, totaling 1111 ms with input tokens climbing to 1,572 (ticket text had to be resent with each query).
Bundled queries cut latency by nearly three-quarters while saving 62% on token costs. Even if a question goes unused in downstream branching logic, the cost of bundling upfront is far lower than repeated request overhead.
Speed, Cost, and Accuracy
Start with pricing and observed latency:
- Official pricing: $0.042 per million input tokens ($42 per billion tokens); output tokens are completely free. Compared to leading frontier LLMs costing $0.20 to $10 per million input tokens plus substantial output charges, Jev lowers invocation costs by factors of several times to several hundred times.
- End-to-end latency: TypeSafe states 70 to 500 ms, with benchmarks executed on the US West Coast where servers are located (Flavio relays official estimates clustering around 100 ms). Tested by Xiaohu from mainland China over transpacific public networks, single-request end-to-end latency typically ranges between 0.25 seconds and 0.58 seconds.
In a 27-question side-by-side demo, Jev took 0.114 seconds and cost $0.000081, while GPT-5.6 Terra took 8.566 seconds and cost $0.013880. The short, dense ticket text favors Jev, and the systems disagreed on one answer, so this demonstrates the speed and cost gap on decision tasks rather than a universal multiplier for every workload.
Across four complete workflow benchmarks, Jev cost roughly two orders of magnitude less, but its agreement rate was about 68%, below roughly 74% for GPT-5.6 sol and 73% for Opus 5. That is the tradeoff: use it for many inexpensive, low-latency decisions, then route uncertain or high-risk cases elsewhere.

How Much Can Jev Truly Save on Your Overall Bill?
Can Jev cut your AI bill by more than half? Technical writer Flavio Copes notes: it depends on where your money goes. He offers a quick calculation formula:
Total Bill Savings Share ≈ Judgment Calls Share of Bill × Savings Share on Judgment Calls
Assuming a company spends $10,000 monthly on AI:
- If $6,000 goes toward text classification, intent routing, safety moderation, and initial screening, and Jev cuts that cost by 95%, monthly savings reach $5,700—a 57% reduction in the total bill;
- If primary spend goes toward generating long-form reports, writing code, or image processing, with pure judgment calls representing only 10% of the bill, replacing all judgment calls with Jev reduces total monthly spend by roughly 10% at most.
When assessing costs, calculate across the entire pipeline: upstream filtering, retry logic, and low-confidence escalations to LLMs or human reviewers must all be accounted for.
Calculate · Same formula as above
Switching to Jev: How Much Can Your Bill Save?
Enter your own numbers. Defaults are from Flavio's example above.
Entire Bill
Monthly savings $5,700; share of the original bill: 57%
60% × (1 − 5%) = 57%
Calculate per call by volume
Per call approx. $0.0000126, total approx. $1.26
Based on official pricing: $0.042 per million input tokens, output tokens are free
Only counts the portion replaced by Jev. Preprocessing, retries, failed requests, manual reviews, and generative steps before and after must be calculated separately.
Real-World Cases from TypeSafe and the Community
The following public demos and open-source projects show the kinds of decision tasks Jev can handle.
Official Demos
Wikiracing: Starting from the Wikipedia page "Baseball," navigate to "Sun" exclusively by clicking links on each page, choosing from hundreds or thousands of candidate links per step. Jev took 0.419 seconds across 3 steps, costing 0.047 cents; Claude Sonnet 5 took 3.724 seconds, 4 steps, costing 3.310 cents; GPT-5.6 Terra took 9.453 seconds, clicking a non-existent link along the way. TypeSafe noted this compared non-reasoning mode on LLMs; reasoning-enabled LLMs perform significantly better.
Jev Plays Doom: The game feeds textual state (weapon stats, enemy distance, orientation) to Jev, which makes ~10 decisions per second: whether to fire, current top priority (e.g., healing), and which direction to dodge. TypeSafe estimates costs at ~$7 per hour, conceding dedicated non-AI game bots likely play better; the demo demonstrates that Jev understands game state, executes instructions, and runs fast enough.
Community Applications
Email Triage (Ryan Vogel): Tested on 1,500 real personal emails, prompting him to post that "this model is insanely good at email triage," gathering 3,530 likes. The video shows his custom email dashboard: classifying category, priority, spam likelihood, and reply necessity per message. At the screenshot moment, 1,534 of 1,701 emails had processed across 8 concurrent requests, averaging 193 ms per email at ~40 emails per second.
Browser Agent (Kyle Jeong, Browserbase): Pairing Jev with Stagehand (an open-source browser automation tool for AI), he posted that a complete task run cost $0.001 almost instantaneously. He described the loop clearly: examine the page, pass DOM structure as context and available actions as options to Jev, let Jev pick the next step, and have Stagehand execute. The video showcases the task: "Log in to a test store, add headlights to cart, view cart, stop before checkout." Jev stepped through username input, password input, clicking login, adding to cart, and opening cart. Twice during execution, logs showed "action confidence below threshold, re-observing page"—rather than guessing blindly, it paused to inspect the page again.
Along the same lines, early demos collected by Flavio show flight booking taking ~7 seconds; developer dax shared a speed preview combining Jev with opencode browser tools on X, gaining 3,725 likes; the browser-use team open-sourced jev-ultrafast, where Jev dictates click targets and calls LLMs only when typing is needed, amassing 5,913 stars on GitHub.
Trading Bot (Jarrod Watts): Built a trading bot feeding pair price data to Jev to determine buy or sell decisions, submitting orders to Kuru's order book on Monad every 300 ms block, complete with a live demo site at jev-trader.vercel.app. The post gathered 4,880 likes and 1.1 million views. While the post claimed live trading, the demo video displayed "dry run" in the upper right, averaging 100 ms per call across 1,840 invocations, occasionally missing a block when latency slipped. This proves Jev is fast enough to keep pace with blocks, not that it generates trading profits: TypeSafe explicitly notes Jev has not received domain-specific financial training.
TypeSafe Typewriter: An interactive demo built by developer Steve Krouse, playable directly at typesafe-demo.val.run. As you type on the left, each keystroke triggers a single call re-evaluating 16 distinct questions: whether it sounds AI-generated, whether it sounds passive-aggressive, flame-war potential, likelihood of reply, tone, urgency, presence of verifiable claims, and more. The bar charts on the right update dynamically, taking 318 ms per invocation in the video.
Framework Integrations: LangChain
LangChain released the official integration langchain-typesafe, explaining in an article which stage Jev handles within an Agent: Agents operate in a loop where LLMs decide actions, tools execute, results are evaluated, repeating until completion; calling LLMs for every micro-decision makes the process slow and costly. Jev steps in to handle these micro-decisions. The integration ships with two prebuilt middlewares: one selects models based on task complexity (dispatching simple tasks to fast models, complex tasks to powerful models); the other inspects risk before tool invocation, intercepting dangerous actions immediately. LangChain noted that coding tools like Claude Code, Codex, and Cursor have long included classifiers to gauge command risk prior to execution, but kept them inside closed-source components; cheap judgment models now allow any Agent to implement this safety layer.
Representative Community Open-Source Projects
The awesome-jev GitHub community list tracks dozens of projects (the curator notes inclusion does not constitute endorsement). Several representative projects include:
- Model router for Claude Code (jev-router): Lets Jev select from candidate models, delegating tasks to the cheapest model that meets quality requirements;
- Ad-blocking extensions (typesafe-adblock / unclutter): Queries Jev element by element on whether a DOM component represents an advertisement or visual distraction, stripping it if true;
- Writing inspection (Sniff Test): Asks Jev 10 boolean questions per paragraph (excessive hedging, repetitive concluding summaries, "not X but Y" phrasing), reporting a median latency of 182 ms;
- Pre-commit guardrails (jev-git): Scans diffs in under a second prior to git commit and push to detect leaked secrets or destructive commands; DiffJury triages PRs by risk to route reviewers;
- Smart home automation (HA-Jev): Home Assistant plugin answering home state queries via probabilities, options, or scale scores;
- Context compaction (fast-jev-compaction): Claude Code plugin with 3,467 GitHub stars. Rather than generating text summaries when context limits approach, it uses Jev to determine line-by-line which tool calls and returns remain relevant, pruning obsolete lines while preserving original text verbatim.
Community Project Index · 46 Projects
What others built with Jev: Browse by use case
Click a category to filter, or search keywords. Click a name to open the project.
46 projects in total
Model & Skill Selection for AI 4
- jev-router★ 151Lets Jev choose among candidate models, assigning Claude Code tasks to the cheapest yet sufficient model.
- jev-agent-skill-router★ 7Lets Jev select skills for Agents, skipping low-relevance skills rather than forcing a match.
- jcm-router★ 2Local proxy: Jev decides which Claude model and what reasoning effort to use for each message.
- jev-router (prismhq)★ 2Open-source router based on LiteLLM; Jev decides which model handles each request.
Agent Safety Guardrails 6
- fx★ 3,061Coding Agent from Vercel Labs; delegates built-in permission audits to Jev instead of calling another LLM.
- jev-axi★ 13Pre-execution checkpoint for Claude Code / Codex: scores each shell command on destructiveness, data exfiltration, remote execution, and security weakening; project self-reports 100% accuracy on 44 labeled examples.
- jev-guard★ 8Guards Agents like Claude Code and Codex against prompt injection and risky operations, with Jev deciding whether to block.
- is-malicious★ 7Runs source code and build files through Jev before installing dependencies, flagging suspicious items for deeper inspection and highlighting problematic files and lines.
- pi-heed★ 2Checks before an Agent modifies anything whether the step was genuinely requested by the user.
- jev-git★ 1Scans changes in under a second before git commit and push to catch secrets and destructive commands.
Code Review 5
- Abide★ 61Monitors every change made by coding Agents, using Jev to flag rule violations; project self-reports that of 39 flagged changes, 10 were confirmed upon independent review.
- Clean Code Judge★ 4Checks 31 code-smell boolean questions on each file in a PR, passing results to a generative model to draft review comments.
- DiffJury★ 3Triages each PR by risk level before assigning appropriate reviewers.
- limpet★ 1Prevents Agents from declaring done prematurely: uses Jev to verify whether completion criteria are satisfied.
- HunchWrite code conventions in plain language and have Jev verify code item-by-item; runs locally or on each PR.
Browser & Web 6
- Browserbase Browser Agent (Kyle Jeong)Jev plus Stagehand: treats page structure as context and available actions as options, with Jev choosing the next step; post states the task cost $0.001.
- jev-ultrafast★ 5,913Ultrafast browser Agent by browser-use: Jev decides where to click next, calling an LLM only when typing is needed.
- Jev Browser★ 114Browser automation with every step decided by Jev, emphasizing significantly faster and cheaper operation than LLM-driven alternatives.
- unclutter★ 107Browser extension: Jev identifies distracting elements on the page and automatically cleans them up.
- typesafe-adblock★ 50Chrome extension: asks Jev one by one whether a page element is an ad, turning ad blocking into a series of boolean questions.
- public-browser★ 8Enables Claude Code and Cursor to control real Chrome with actions decided by Jev; project self-reports ~30% fewer tokens and ~25% lower costs.
Writing & Content 4
- Sniff Test★ 14Writing checker: asks Jev 10 boolean questions per paragraph (stacked hedges, repetitive summary endings, 'not X but Y' constructions, etc.), threshold 0.7, project self-reports 182 ms median latency.
- pagegrade★ 1Scores each webpage section on clarity, copy quality, and SEO.
- JevSlopScores note.com articles across 8 dimensions in a single request, calculating a 0 to 100 'slop score'.
- citation-verifierVerifies academic citations: Claude locates cited source sentences, Jev determines support, and a human makes the final call.
Productivity & Data 6
- Email Triage (Ryan Vogel)Tested on 1,500 real personal emails, evaluating category, priority, spam status, and reply need per email; video shows 8 concurrent requests averaging 193 ms per email.
- Notra★ 175Marketing analytics platform: moves brand exposure classification judgments from LLMs to Jev, boolean threshold 0.5, targeting 300 ms median latency.
- Email Intent Routing★ 4Uses a Choice question per incoming email to classify invoice vs. general email, routing to the matching workflow.
- jev-curate★ 3Filters synthetic datasets using Jev boolean questions and confidence scores, writing accepted and rejected items separately to disk.
- CV screener★ 1Screens an entire folder of resumes against configurable criteria; updating criteria requires no additional API cost to rescore.
- typeful-triage★ 1Issue triage dashboard for open-source projects: queries type, severity, urgency, duplicates, and next steps per issue, recording manual edits.
Agent Context Management 3
- fast-jev-compaction★ 3,467Claude Code plugin: when context nears capacity, avoids summarization and instead lets Jev determine line-by-line which tool calls and results remain useful, retaining original text.
- yoshi★ 12Proxy layer for Claude Code and Codex: has Jev identify which historical dialogue is still needed before pruning the rest.
- wakegateBefore scheduled wake-up of dormant Agents, asks Jev whether waking is warranted, avoiding waking the LLM unnecessarily.
Games & Fun 7
- Jev Trader (Jarrod Watts)Evaluates buy or sell every 300 ms block, placing orders on Monad's Kuru order book; demo video labeled dry run.
- HA-Jev★ 16Home Assistant smart home integration: answers queries about home conditions using probabilities, options, or scores.
- jevinci★ 14Lets Jev guess pixel colors in parallel to paint; higher confidence yields broader brush strokes.
- pacman-jevPac-Man: open-source implementation where Jev decides which direction to move at each step.
- tetris-aiBrowser Tetris playable by a built-in planner, Jev, or any chat model.
- Jev PongPong game where the model decides each paddle move, pitting Jev head-to-head against LLMs.
- robo-harnessRobotic arm testbed: Jev selects next joint movements from candidate actions, complete with spending limits.
Benchmarks & Counter-Findings 2
- jevcal★ 5Uses your labeled data to fit confidence thresholds achieving target accuracy per question, calculating how many requests still escalate to LLMs; automated checks alert when model updates invalidate thresholds.
- "Jev Reranking Is Not Free Lunch"A benchmark across 33,047 catalog items and 164 real queries concluded that standalone Jev reranking did not beat vector retrieval.
Open Source Replications 3
- NanoJev★ 4390.6B-parameter open-source reproduction: directly outputs full probability distributions, including training pipeline, weights, and dataset.
- Laya★ 301Open-source non-autoregressive judgment model answering all three question types in ~35 ms per forward pass.
- kev★ 212Mini reproduction built on Qwen2.5-0.5B, trainable and runnable on a MacBook.
Curated from GitHub community list yibie/awesome-jev (scraped 2026-09-19) and four posts on X; Chinese descriptions translated from source listings by XiaoHu, star counts reflect GitHub data on scraping day. Self-reported metrics lack independent verification; list author notes inclusion does not imply endorsement.
Hands-On Tests We Conducted
The following use cases were executed by us directly on Jev, with authentic request and response metrics. Input provenance is explicitly labeled: tests marked "real data" utilized genuine news items from Xiaohu's information feed; tests marked "example input" used text we authored for testing purposes, not real user data.
Scoring Clickbait in Headlines (Real Data)
We passed 30 real Chinese headlines from our news feed (mostly machine-translated from English originals) to Jev in a single request, asking two questions per headline: clickbait severity (Score question: faithful summary / catchy but accurate / exaggerated, fear-mongering, or curiosity gap) and whether the headline contains specific numbers, names, or facts (Boolean question). All 30 headlines and 60 questions completed in a single request taking 1.2 seconds across 4,923 input tokens.
- The highest clickbait score was "Is AI an Elite 'Crime Spree'? A Critique of AI Abuse and Power Concentration" ("AI is an elite crime spree") at 1.67, with a specific fact probability of only 0.13;
- "Will AI Really Kill Us? Frequently Asked Questions" ("Could AI really kill us all? Your questions, answered.") scored 1.32, with fact probability 0.13; "DeepSeek's Crazy New Architecture" ("DeepSeek’s Insane New Architecture") scored 1.16;
- The lowest clickbait scores were "What is AIOps? AI Empowers IT Operations" ("What is AIOps?") at 0.04 (confidence 0.94) and "In-Depth Analysis of LLM Model Quantization Formats: How to Choose Between GGUF, GPTQ, AWQ, and EXL2?" ("GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)") at 0.19 (fact probability 0.95).
Borderline headlines exhibited notably low confidence: "Google Gemini Accidentally 'Jailbreaks' During Security Testing, Successfully Infiltrating Three Real Companies" ("Google's Gemini also accidentally hacked three real companies during security testing") scored 1.21 with confidence near 0, reflecting model uncertainty. Production application: headlines scoring above 1.5 without specific facts receive a "clickbait" tag; borderline items bypass automation.
Fact-Checking LLM Summaries (Source Text is Real News, Checked Sentences are an Example We Wrote)
The source text was a real news feed summary: "Qwen releases next-generation native omni-modal model Qwen3.8-Omni-Flash, supporting text, image, audio, and video inputs alongside a 1M token context window, improving the average score across 29 benchmarks by over 25% compared to Qwen3.5-Omni-Plus, with reduced hourly audio input pricing." We intentionally authored 4 statements for Jev to evaluate line by line: two true, one exaggerated, and one unmentioned in the source. Each asked a Choice question: supported by source / contradicts source / not mentioned in source. A single request completed in 293 ms:
- "Context window is 1 million tokens" → Supported by source (confidence 1.0);
- "Its average score across 29 benchmarks improved over 50% compared to the previous generation" → Contradicts source (confidence 1.0);
- "It has open-sourced model weights" → Not mentioned in source (confidence 1.0);
- "It accepts direct video inputs" → Supported by source (confidence 1.0).
Production application: LLMs generate, Jev verifies; statements flagged as "contradicts" or "not mentioned" escalate to human editors.
Detecting Sarcasm (Example Input)
Three statements we wrote, each queried with three questions: whether it is sarcastic, whether the author is satisfied, and emotional intensity.
- "Your service is truly wonderful, no one has replied to me in three days." → Sarcasm 0.96, Satisfaction 0.03;
- "Customer support resolved my issue in ten minutes, truly wonderful service." → Sarcasm 0.08, Satisfaction 0.97;
- "Order shows delivered, but I haven't received the package." → Sarcasm 0.04, Satisfaction 0.07.
Phrases like "truly wonderful" that praise literally while complaining in context routinely bypass keyword filters. Note that this represents a small three-sentence evaluation.
Extracting Final Meeting Times from Chat Transcripts (Example Input)
A three-line exchange we wrote: "I have meetings Wednesday afternoon, does Thursday morning work?" "Thursday morning doesn't work for me, how about Friday at 3 PM?" "Works for me, let's do Friday 15:00 on Tencent Meeting." The script extracted the three proposed times into options (plus an "Agreed time not reached" option) and asked Jev which was finalized. In 281 ms it selected Friday 15:00 with 1.0 confidence, demonstrating it understood the first two options were rejected; the meeting tool was classified as Tencent Meeting with 1.0 confidence. Resolving calendar dates and scheduling entries is left to deterministic code.
Assessing Command Risk Before Agent Execution (Example Commands)
We packaged 6 common commands into a single request, asking whether each was read-only, reversible, or irreversible, taking 306 ms:
ls -la,git status→ Read-only (confidence 1.0, 0.99);rm -rf node_modules→ Reversible (probability 0.86, confidence 0.78, recoverable by reinstalling dependencies);git push --force origin main,curl ... | sh,psql -c 'DROP TABLE users;'→ Irreversible (confidence 0.98 to 1.0).
Production application: auto-approve high-confidence read-only commands, escalate everything else for confirmation. Flavio suggests logging decisions without blocking initially, expanding auto-approval once sufficient real-world samples are gathered. Under LangChain, this workflow exists as prebuilt middleware.
Multi-Dimensional Topic Scoring (Real Data)
Instead of prompting models for a vague composite score, decompose evaluation into individual dimensions for Jev to judge separately, combining them with weighted formulas in code. We tested 4 real news stories across three dimensions: contains explainable mechanism or methodology (Score), immediately actionable for readers (Score), purely financing news (Boolean).
- Rules enforced in code: pure financing announcements (probability > 0.5) are rejected immediately; remaining dimensions split weighting equally;
- Qwen new model scored 0.468, retained; Manus funding received a 0.91 "pure financing" probability and was filtered out;
- Crusoe funding scored 0.69 on "mechanism" due to mentions of data centers; weighted scoring alone would have ranked it second above Astra for Law, but the "pure financing 0.81" check intercepted it.
Decomposing dimensions makes scoring and filtering transparent; adjusting criteria weights requires changing a variable in code rather than re-running model calls.
Known Limitations and When Not to Use It
TypeSafe published a dedicated "Known Limitations" page for the current jev-1.13 release. Combined with our testing, the most frequent pitfalls include:
Do not use it for math or counting: Jev is not a calculator. When asked to count occurrences of the word "banana" in an English word list (correct answer: 4), it selected the right option with only 0.56 probability, giving 0.40 to "5" with 0.45 confidence. TypeSafe notes error rates rise as counts increase. Calculations, comparisons, and discounts belong in code.
Do not use it for direct date comparisons: We tested two simple cases (checking whether an order timestamp fell within a campaign window), and it answered correctly; however, TypeSafe warns date comparisons are unreliable, failing frequently on relative expressions like "last Tuesday" and mixed date formats. The safer approach has Jev extract the year, month, and day (tested at 1.0 confidence for month extraction, 0.97 for day extraction), leaving comparison logic to code.
It does not write text—it only selects from candidates: To extract amounts, email addresses, or order IDs from text, do not ask it to "state" the value; extract candidate values first and have Jev choose. In a complaint containing four figures (399 yuan, 50 yuan, 349 yuan, 89 yuan), a single regex extracted all amounts as options. When asked which amount the customer sought refunded, Jev selected 89 yuan in 249 ms with 1.0 confidence. Flavio analogizes: ask it to pick a card from a deck, not name a card from scratch.
Phrasing must be explicit: Jev interprets questions literally without inferring unstated assumptions. When questions and option descriptions conflict (e.g., where "Yes" in a boolean query represents a negative outcome), accuracy degrades. Frame questions as if briefing a new intern: clear, direct, and unambiguous.
Reciprocal question probabilities do not necessarily sum to 1: On a ticket stating "charged twice for the same order," asking "Is the customer requesting a refund?" yielded 0.56, while asking "Is the customer requesting something other than a refund?" yielded 0.30, summing to 0.86. Each question is computed independently; do not infer one from the other.
Avoid overloading irrelevant context: Extraneous content degrades accuracy (TypeSafe terms this "context rot"). Pre-filter inputs to provide only text pertinent to the specific judgment.
If deterministic code can handle it, do not use a model: As Flavio states, a free if statement is always superior to a potentially fallible model call. Furthermore, tasks requiring generative writing or multi-step reasoning belong with LLMs.
Recommended Progressive Adoption
When integrating Jev into existing workflows, the safest route begins with shadow observation rather than granting immediate execution authority:
- Keep existing rules: Retain existing deterministic business logic unchanged;
- Shadow logging in parallel: Attach a parallel Jev call at critical judgment nodes, recording predictions, scores, and confidence to logs without impacting production paths;
- Analyze accuracy and establish thresholds: Gather real-world records to evaluate Jev's accuracy across confidence tiers, defining thresholds aligned with your operational cost of error (Flavio recommends at least 20 ground-truth examples for exercises);
- Gradual cutover: Begin by fully automating high-confidence, low-risk paths, routing remaining cases to human review or LLM fallbacks.
Flavio suggests a practical starting point: select a single micro-judgment currently handled by static rules or brittle regex (routing, approval, skipping), have AI swap it for a Jev query using the TypeSafe skill, run it in parallel logging confidence for a week, and cut over only once performance is proven.
Members can copy or download the full Markdown, and let their AI subscribe and ask.
Found this useful? Leave your email — every new explainer, the moment it's out. Unsubscribe anytime.