AI Saved 700 Agents' Worth of Work — Klarna Says Quality Dropped
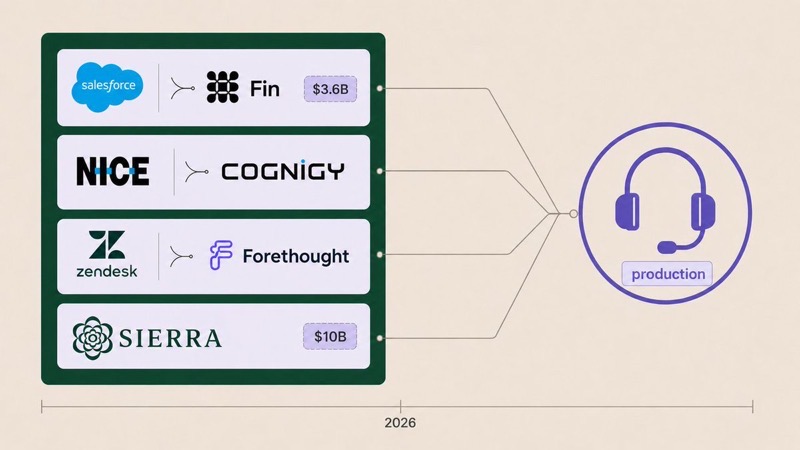
- Around June 2026, Salesforce acquired Fin for roughly $3.6B, NICE bought Cognigy, Zendesk bought Forethought, and Sierra hit a $10B valuation — AI support poured into enterprise core budgets all at once.
- In February 2024, Klarna disclosed that its AI support covered two-thirds of requests, the equivalent of 700 full-time agents; about a year later the CEO admitted an over-focus on cost led to "lower quality."
- Alibaba's four-week randomized trial across 2.56M conversations showed AI sped up problem identification by 8.2% and lifted on-the-spot satisfaction 1.2% — but the odds of contacting again within 3 days for the same issue didn't budge statistically.
- The four mainstream metrics today (auto-resolution rate / handling time / escalation rate / cost per contact) all quantify savings from the company's angle — and a confidently wrong answer can move every one of them the right way.
- Author Lucius proposes a new framework: Support Quality = Resolution × Context × Trust × Learning × Experience — replacing cost savings with the full user journey as the core measure.
One month, four big deals, and AI support suddenly became the main arena
On June 15, 2026, Salesforce announced it would acquire AI-support company Fin for roughly $3.6B. Around the same window, NICE bought Cognigy, Zendesk bought Forethought, and Sierra closed a new round at a $10B valuation.

Klarna: every metric green, then a year later the CEO says "we got it wrong"
The old scorecard once handed the first generation of AI support a gorgeous report card.
In February 2024, Klarna announced that in its first month live, its AI assistant handled 2.3M conversations, covering about two-thirds of support requests — a workload equal to 700 full-time agents. Average resolution time fell from 11 minutes to 2, and the company expected the year's profit to improve by about $40M as a result. For anyone managing a support budget, these numbers are as good as it gets.

- 2.3M first-month conversations
- ≈700 full-time agents' worth
- 11→2 min resolution time
- $40M projected profit gain (self-estimated)
The company "focused too much on cost" and ended up with "lower quality." CEO Sebastian Siemiatkowski re-emphasized human agents.
Both statements hold at once, without contradiction. AI really did handle more conversations, really did push costs down. The catch is how you define "success."
Today's scorecard only measures how much money the company saved
Auto-resolution rate, average handling time, escalation rate, cost per conversation — all four mainstream metrics are quantified from the company's side. They can tell you how much the queue shrank and how many tickets humans dodged, but they can't answer whether the user got the right answer, whether they were forced to repeat the same thing, or whether anyone took the hard question.
Here's a key term — deflection rate: the share of conversations the AI resolves itself without passing to a human; as long as it isn't handed off, it counts as "success."
Like steering people in line toward a self-service kiosk and calling it "service complete" — whether they actually got anything done, no one records.
Once "deflection rate" becomes the goal, the product gets pushed to do a few things: keep the user inside automation as long as possible, delay handing off to a human, cram fuzzy questions into existing answers, and close the easy-to-close tickets first. Every one of those makes the automation metrics look better, and every one can make the user's experience worse. A confidently wrong answer still counts as "success."
The user is stuck in the automated flow repeating themselves while the system logs several "efficient responses." Even if the user finally gives up, handling time and ticket volume both look fine. The first generation of AI support did automation well; its weakness was mistaking the cost the company saved for the outcome the user got.
Alibaba's 2.56M-conversation trial reveals one precise gap in the numbers
In a four-week randomized trial, Alibaba tracked 5,940 agents, about 2.56M conversations, and 390K user ratings. After plugging in generative AI, several metrics improved together.

The first four all improved; only the last one — the odds of contacting support again for the same issue within 3 days — was not statistically significant (no detectable change). And it is the only metric in the set that measures whether the problem was actually solved.
It got faster, users felt better in the moment, but the share who came back didn't drop. Speed and satisfaction explain only part of the experience; whether the problem moved toward a result is a separate matter.
The new framework: from "how much we saved" to "did the user's journey finish"
If enterprise support is to carry the user's whole journey, the scorecard has to cover the whole journey. Lucius breaks support quality into five dimensions measured together.
The last generation's dashboard counted how many replies the AI sent and how many labor hours it saved. This framework answers five questions: Did the user get a result? Did the context keep up? Did this exchange burn trust? Did this time make next time better? Is the user still willing to stay in the community? Open each layer to see what the old system measured and what this layer adds.
1ResolutionDid the problem reach a result?+
Deflection rate, handling time — only whether the queue shrank.
Task success rate, first-contact resolution, recontact rate, ticket-reopen rate, plus whether there's a clear owner and next step.
2ContextDid the information keep up?+
How big the knowledge base is, how many docs got stuffed in.
A live snapshot of company state + user state — whether the content is current, bounded, and actionable, not fluent answers that happen to be an old version.
3TrustDid this exchange spend down the relationship?+
Barely measured — the AI replies in the company's name, so even a wrong sentence counts as a company promise.
Whether it stops when info is missing, whether it over-promises, whether it can route sensitive questions to a private flow, whether it keeps a full evidence trail on refunds/promises/compliance, and whether accountability is traceable when something goes wrong.
Per ITPro citing Sinch's survey, 74% of companies surveyed have rolled back or shut down a support AI agent due to governance failures. Top causes: customer-data leaks 31%, hallucination or brand risk 22%, lack of auditability 16%. What companies care about isn't whether the AI seems human — it's whether they can safely hand service over.

4LearningDid this time make next time better?+
Not measured — every conversation is one-off, done the moment it's handled.
Whether uncertain questions become new system knowledge; whether the pitfalls, sticking points, and final breakthrough from this session settle into reusable experience for next time.
5ExperienceWill the user still stick around?+
A single satisfaction score that papers over everything that happened along the way.
Whether the user is understood right where they are, or kicked to another entry point to log in again, fill out a form, and retell the problem. Every public reply shows how this organization treats people who ask for help.
An example: a beginner builds a project from their own idea for the first time
In a tooling community, a beginner builds a project from their own idea for the first time — wiring a workflow platform to a low-code tool to make a page where you fill in article content and API credentials and, with one click, push the article to a drafts box. The project got stuck on return structures, API fields, variable bindings, rendering results, and a 60-second timeout, and the whole chain finally ran end to end. When it was done, he asked the community's AI persona to walk back from the very first message and organize the whole thing into a reusable path — project goal, overall architecture, five stages, every error, current status, and next step. He said it was the first time he felt he could build something from his own idea, that the AI seemed to hold the entire process in its head and carry him forward. Old-style support that only searches a database for answers can't sustain that kind of end-to-end coaching.
Real "resolution" starts with whether the user dares to speak up
Resolution doesn't start with "did the AI answer" — it starts with whether the user is willing to speak up.
Educational psychology has a related concept, question-asking anxiety: when people feel the other side is authoritative, formal, and might judge them, they start vetting their own question — is it too dumb, will it look amateur, am I bothering someone. Support is the same. An entry point that's too formal and cold makes users first weigh whether they're "qualified" to ask; an official window that only serves canned answers bottles up many early questions in the user's head. By the time they actually come for help, the problem is usually already more complex.
Speed helps. Right after the user speaks up, the problem is still fresh, emotions haven't festered, and the missing context is easiest to fill. If the system at that moment tosses them to another entry point, demands a form, or makes them wait for email, they may not ask next time. Real resolution is the system showing the user a path to a result: who's responsible, what happens next, when there'll be an update, where it's stuck now. Passing the user to another person, another channel, another form only proves the problem was moved elsewhere; if the user still doesn't know who's handling it, when, and how far along, the problem hasn't moved forward.
This echoes exactly the gap in Alibaba's trial: the AI made things feel better in the moment, yet the recontact rate didn't drop — proof that "answered fast" isn't "answered right, and told you the next step."
The 8 signals Lucius uses to measure "resolution"
Task success rate · first-contact resolution · recontact rate · ticket-reopen rate · time to resolve · escalation success rate · owner-assignment rate · whether the next step is clear (with a bit of subjective judgment).
Context isn't the knowledge base — it's two live tracks running at once
Context holds two records changing at the same time: company state and user state. Miss either one and you answer new questions with old answers.

Many companies take pride in the sheer size of their knowledge base. Production forces a harder question: does this content still hold? Features change, prices change, policies change, staff shift their messaging, users get new promises. Once the docs fall behind, the AI can still answer — it just delivers old answers in fluent language. Context is useful only if it's current, bounded, and actionable.
Here's a term to keep straight — working memory: the running tally the AI keeps while handling this ticket — what it has gathered, which actions it has taken, which step it's stuck on now.
It isn't the medical chart (the knowledge base) — it's the live operative record of "which step of this surgery we're on right now."
In Nubank's support system serving over 100 million users, instructions, flows, macros, tool descriptions, and working memory are managed as separate, independently versioned components. Working memory records the info gathered, tool-execution results, and which step it's on now. When a low-confidence question is handed to a human, the entire conversation context goes with it, so the user doesn't have to play "context courier." This is closer to production-grade context management than cramming more docs into the prompt: the system needs to know both the current facts and the task's current state.
Update the knowledge base once a month, and the changes in between get answered with old answers
Same context, different maintenance cadence — different odds the AI answers new questions with old answers.
Traditional knowledge-base maintenance gets stuck here: many teams used to update docs only once a month, and even after updating couldn't guarantee the AI retrieved the right entry — so they chopped docs into smaller and smaller fragments. Chopping doesn't necessarily make retrieval more accurate; it creates more similar fragments, making it harder for the system to judge which one still holds.

The team doesn't hand-maintain docs; Lucius routes uncertain questions to them, they answer as if replying to a message, and the system learns. Flip it around: if those 400 updates were compressed into one manual cleanup a month, the big batch of new messaging, exceptions, user promises, and product changes in between would vanish in the gaps. A system that can't reach this context can only answer new questions with old answers.
Demand has woken up; the companies that can deliver haven't caught up
The market sees the direction, but the migration isn't done. That gap is the window for whoever moves first.
Most companies are still stuck in old systems: docs scattered everywhere, past conversations buried in channels, support flows disconnected from the community floor, human handoffs with no evidence trail, AI replies lacking boundaries and memory. Many misread the AI-support problem as "not human enough," so they endlessly polish tone, persona, avatar, and greetings — but what users care about is something else: does the system actually understand this problem. Per Lucius, in support communities using its system, the share of users who proactively ask for a human can be below 0.1% (Lucius's own sample).
Once a user has seen the experience of "the moment I speak up, the system knows who I am, no repeating, remembers where I got stuck last time, and calls a human when it should," old-style support will feel as dated as dial-up. Companies still using last-gen chatbots to stall users will eventually have to catch up — and by then it won't be a tech-procurement problem, it'll be a trust-repair problem.
The first generation of AI support was built around the company; the next will be built around the user's whole journey.Lucius / X · June 29, 2026
AI Support Cut Costs — but It's Grading the Wrong Thing
AI-support vendor Lucius recaps: Klarna's year-long reversal and Alibaba's 2.56M conversations both hit the same measurement blind spot — one illustrated page.
↓ Read it in one page · one figure moves
AI support means using AI bots instead of people to answer customers' after-sales questions. Within one month in June 2026, four big acquisitions in a row — Salesforce, Zendesk, and others — shoved it straight into big companies' core budgets.
But the scorecard used to judge whether it's any good tallies everything from the company's side.
✘ It can't compute: whether the user got the right answer, whether they were forced to retell the same thing, whether anyone took the hard question
The four mainstream metrics (auto-resolution rate / handling time / escalation rate / cost per contact) all count money on the company's side; whether the user's issue got solved, it simply doesn't measure.
Start with a real example that puts the contradiction on the table.
- First month handled 2.3M conversations, covering two-thirds of requests
- Worth about 700 full-time agents
- Average resolution time 11 → 2 minutes
- Expected about $40M more profit that year (company's own estimate)
The company rehired human agents. The CEO admitted "focusing too much on cost" bought them "lower quality." Same system, two conclusions.
The savings are real, the quality drop is real, and both holding at once can only mean the scorecard measures the wrong thing. Why can they coexist? See the animated figure below.
Xiaohu's refund issue enters automated support. The industry has a default rule: as long as the bot catches it itself and doesn't hand off to a human, it counts as a "success" (that ratio is called the deflection rate). So what happens next makes every company metric look better.
Xiaohu's refund issue spins in automated support and is finally abandoned, yet the system logs it as one "efficient response" — that's how Klarna's 2.3M conversations in a month racked up such pretty metrics.
Alibaba ran a four-week randomized trial, its sample big enough to prove the point. First, translate the official numbers into a feel for time: replies really did get faster.
Fast is real, but it's only half the experience.
Only that last number didn't move: the share of Xiaohus who came back for the same issue didn't drop at all. Answered fast isn't actually solved.
AI support just squeezed into core budgets.
the biggest at $3.6B.
no human handoff.
the bot still circles in place.
that's how the pretty numbers happened.
2.56M conversations.
the recontact rate."
the only "really solved?" metric.
Trust × Learning × Experience
but "did the issue finish."
- × All numbers are company-measured
- × No third-party replication
- × The new yardstick is also vendor Lucius's
the problem's really solved."
Ask one more thing:
Members can copy or download the full Markdown, and let their AI subscribe and ask.
Found this useful? Leave your email — every new explainer, the moment it's out. Unsubscribe anytime.