Google Releases Nano Banana 2.1: More Natural Images, More Coherent Editing
Retains Flash-level efficiency while improving image quality, typography, subject consistency, and local editing, with support for multiple reference images, search, and video input.
Google has released Nano Banana 2.1 (API model name gemini-nano-banana-2.1), an efficient image generation and conversational editing model. As an upgraded version of Nano Banana 2, it is built on the Gemini 3.6 Flash architecture, maintaining Flash-level responsiveness and cost efficiency while introducing the following key features:
- Natural imagery and microscopic textures: Improves microscopic textures such as translucent materials, morning light on snowfields, fur and fabrics, and oil painting brushstrokes, enhancing realism and detail rendering across different resolutions;
- Text typography and design alignment: Enhances character rendering clarity, whitespace control, and geometric layout compositions, facilitating direct generation of posters, charts, and page design drafts with structured visual hierarchies;
- Multi-reference subjects and continuous editing: Supports input of up to 14 reference images in a single request (official specifications support facial consistency for up to 4 characters and detail fidelity for up to 10 objects), and supports iterative adjustments across conversation turns;
- Masking and ink-based repainting: Creators can circle subjects with doodles to selectively replace the surrounding background and atmosphere while preserving the original contour and position;
- Extreme aspect ratio support: Supports 15 aspect ratios ranging from 1:1 to 1:8 and 8:1, fixing tiling seam artifacts on long images at 2K and 4K outputs;
- Search grounding and thinking reasoning: Supports integration with Google Web and Image Search to supplement factual or visual references, and balances generation quality and latency via a configurable Thinking process.
More Natural Image Texture: Discerning Light, Shadow, and Microscopic Textures
In Nano Banana 2.1, "more natural images" is reflected in material textures, lighting gradations, and artistic brushstrokes—not merely higher pixel counts. The following generation examples showcased by Google make these changes easier to observe:

The translucency and reticulated veins of the dried petals, together with the background blur, create the feel of a macro photograph.

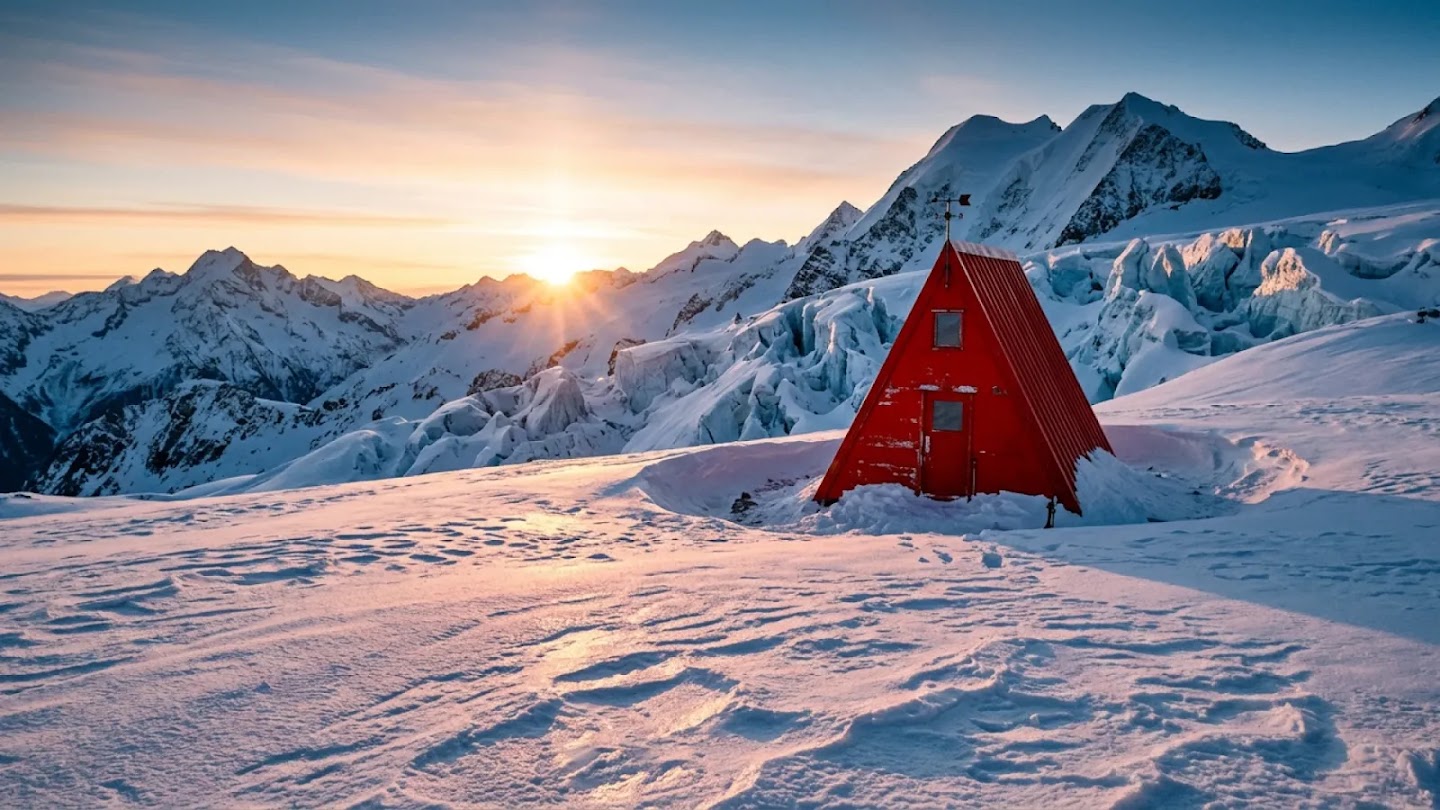
In natural landscapes, the warm reflections cast by low-angle sunlight and the cool tones of glacial shadows establish a distinct contrast, making the illumination on the snow and structure appear more natural.

In scenes depicting interactions between people and animals, distinct materials such as heavy garments, skin texture, and shaggy fur retain their individual tactile differences.

In non-photographic artistic styles, the model can render thick, layered paint brushwork textures according to the prompt, conveying the dynamic motion of surging waves. These examples also demonstrate how prompts can guide lighting, texture, and style.
Long Images and Banners: First Fixing Unnatural Seams
When producing vertical strips, panoramic banners, or ultra-wide posters, the previous Nano Banana 2 exhibited "tiling artifacts" (unnatural repeating patterns or grid seams) in 2K and 4K outputs for certain extended aspect ratios.
Nano Banana 2.1 addresses these output issues with several updates:
- Comprehensive coverage of mainstream and extreme aspect ratios: Supports 15 aspect ratios, ranging from standard 1:1, 3:4, and 16:9 to extreme vertical strip and panoramic formats (including 1:4, 4:1, 1:8, and 8:1).
- Fixes tiling artifacts on specified extended aspect ratios: When outputting panoramas or ultra-narrow compositions at 2K and 4K tiers, the model maintains overall visual continuity, effectively eliminating artificial seam lines and sliced segmenting along extended frames.
- Tiered output resolutions: Outputs default to 1K resolution; creators and developers can freely specify 2K or 4K images depending on use cases, accommodating everything from quick social media previews to high-precision asset delivery.
Text and Layout Better Aligned with Imagery
When applying AI images directly to posters, e-commerce ads, or UI prototypes, the primary pain point has often been garbled, blurry, or illegible text. Nano Banana 2.1 strengthens typographic alignment and character rendering capabilities, better organizing visual hierarchy, negative space, and font styles according to prompts.

Beyond standalone art posters, when creating complete series of assets or cohesive visual drafts, the three capabilities demonstrated in the official Nano Banana 2.1 gallery—text rendering, subject preservation, and localized editing—serve distinct roles:
- Text typography: As shown in the design mockup examples, the model organizes font sizes, negative space, and geometric grids per the prompt, providing posters or page drafts with clear typographic hierarchy and reducing friction in downstream typesetting;
- Subject preservation: As demonstrated in the official product gallery, the model preserves the core product's silhouette and gold hardware while placing it across varied lighting environments, helping prevent distortion of flagship products across marketing campaigns;
- Localized editing: As illustrated in the official ink-based editing example, by circling a subject with doodles, the model can rapidly replace surrounding environments while preserving the subject's original microscopic texture and form, facilitating fast exploration of different atmospheres and compositions around the same focal point.
Nano Banana 2.1 also supports Google Web and Image Search (Search Grounding, incorporating search results as supplementary reference during generation), enhancing text and layout performance in infographics. Whether the factual content within an image is accurate must be evaluated separately from its visual design.
At the default 1K resolution, fine print remains prone to blurring; lengthy passages and full-page text also remain weak points. While text typography has improved, word-by-word proofreading remains an essential step in asset finalization.
Changing Scenes While Keeping Products and Characters Identifiable
Maintaining consistent characters and unaltered product features is a critical prerequisite for storyboards, illustrated books, and brand marketing. In Nano Banana 2.1, multi-image reference fusion has been further formalized:
- Input support for up to 14 reference images per request: Creators can supply multiple assets within a single prompt for comprehensive synthesis by the model.
- Consistency scope for reference subjects: In multi-image fusion scenarios, official API specifications indicate support for facial and feature consistency for up to 4 characters, as well as detail fidelity for up to 10 objects. This defines the supported reference scope; variations in character features can still occur within this range.

For product visual expansion, creators need only provide an isolated product shot on a white background to reposition the item into commercial studios, outdoor landscapes, or artistic display plinths via prompts, while better preserving core product features such as hardware and silhouette.
Beyond single-product scene migration, the official gallery also showcases multi-person, multi-reference synthesis:

Compared to simply prompting "multiple models posing before colorful architecture," multi-angle references for people and clothing provide much more specific requirements for appearance, color blocks, and styling, which the model then integrates into a unified scene.
The multiple reference sets and group photo in this example illustrate asset fusion. The reference scope listed in the API documentation remains up to 4 characters and 10 objects; the appearance of more individuals in an image does not guarantee that each person's identity is consistently preserved.
Circling Subjects to Make Background Modifications More Explicit
For creators requiring refined image touch-ups, Nano Banana 2.1 offers environment repainting based on doodles or masks (Mask/Ink-based Editing). By drawing a selection or sketching around the subject on the original image and prompting to "preserve the subject's outline and position while replacing the background," the model can execute a stylistic overhaul.

When modifying finished images, two known issues warrant attention:
- Pose lock: When editing people or dynamic subjects, the model occasionally adheres too rigidly to the physical skeletal pose of the input image, failing to break away from the original posture when prompted to "turn the head" or "change gestures."
- Residual markings: Mask or ink-based edits may execute instructions only partially, or leave the hand-drawn markings visible in the output image.
Iterative Editing and Broader Input Modalities
Beyond single-turn generation, current official API documentation recommends multi-turn conversations as the standard approach for iterative image generation. Creators can continue modifying existing results:


In the diagram example provided by the official documentation, the user first generates an English photosynthesis infographic, then in the subsequent request references previous_interaction_id (the identifier for the previous interaction) to request changing only the text in the image to Spanish. This conversational editing preserves the primary composition and visual framework of the image, although localized details such as the shape of the sun may still undergo minor changes rather than the entire image remaining strictly pixel-identical. The official documentation also recommends that if you need to generate diagrams containing text, it is best to first finalize the textual content within the conversation before asking the model to render it onto the image; officially recommended languages for high-quality rendering include Simplified Chinese (zh-CN), English, and Spanish. Multi-turn conversation is an existing capability of the series, and 2.1 further improves consistency during iterative editing.
Beyond standard text and images, the model supports broader multimodal and external inputs:
- Google Search Grounding: The model supports integration with Google Web Search and Image Search. Web search supplies up-to-date external factual grounding for charts such as weather forecasts or recent trending topics; image search incorporates web imagery as visual composition and style references. Both can be enabled independently or combined in a single call. Note that image search explicitly does not support retrieving photos of real individuals from the web as image generation references.
- Video-to-Image: Creators can provide public YouTube links or upload local video files. The model analyzes visual themes and key events across video frames, then combines them with text prompts to generate video thumbnails, promotional posters, or plot summaries. The output here consists of static images generated with reference to the video content. The previous Nano Banana 2 and 2 Lite also support video input.
Which Tasks Improve More Noticeably with Thinking Enabled
Nano Banana 2.1 supports configurable thinking levels (Thinking Levels, including minimal, medium, and high), representing a trade-off mechanism between generation quality and inference latency, with medium as the default setting. When confronted with complex compositions or multi-subject prompts, the model generates up to two intermediate images during the thinking process to experiment with composition and deduce logic, with the final image delivered as the completed result. Notably, in the current Gemini API, the thinking process is enabled by default and cannot be disabled; calls automatically incur thinking tokens. "No Thinking" listed in the official model card is an evaluation condition; the current API permits adjusting thinking levels but provides no switch to turn thinking off.
According to side-by-side human evaluation (SxS human eval) results published in Google's official model card, the human preference Elo scores across various tasks are as follows:
| Evaluation Task (SxS Human Preference Elo) | 2.1 Thinking | 2.1 No Thinking | 2 Thinking | Pro |
|---|---|---|---|---|
| Overall Preference | 1050 ± 14 | 1015 ± 13 | 990 ± 7 | 935 ± 8 |
| Infographic Design | 1048 ± 17 | 1001 ± 17 | 961 ± 12 | 912 ± 12 |
| Multi-Character | 1106 ± 14 | 1068 ± 14 | 978 ± 10 | 1011 ± 10 |
| Mask/Ink | 1049 ± 15 | 1042 ± 16 | 965 ± 12 | 927 ± 12 |
| Product Consistency | 1024 ± 18 | 981 ± 18 | 955 ± 22 | 965 ± 14 |
| Style Transfer | 1062 ± 20 | 1036 ± 17 | 991 ± 12 | 990 ± 12 |
| Multi-Reference Editing | 1066 ± 22 | 1041 ± 20 | 988 ± 13 | 989 ± 12 |
On the factuality evaluation dimension, Google employed single-sided automated evaluation (Single sided AutoRater), whose methodology differs fundamentally from human preference Elo and is listed separately below:
| Evaluation Task (Single-sided AutoRater Factuality Score) | 2.1 Thinking | 2.1 No Thinking | 2 Thinking | Pro |
|---|---|---|---|---|
| Infographic Factuality | 0.521 | 0.328 | 0.179 | 0.265 |
From practical application scenarios, "generating a single good image" and "modifying the same subject or synthesizing multiple individuals" represent fundamentally different tasks:
- "Generating a single good image": Corresponds to single-turn text-to-image and overall preference. The model needs only to interpret the prompt freely to produce a visually pleasing, harmoniously composed standalone image, without rigid comparison against sequential reference assets, offering generous fault tolerance;
- "Modifying the same subject or synthesizing multiple individuals": Corresponds to tasks such as multi-character and product consistency. These require the model to preserve specific silhouettes, materials, and features across multi-image inputs or localized repainting, or even maintain distinct identities for multiple entities within the same frame; noticeable distortion or blending features between characters disrupts coherence.
In this benchmark suite from Google, 2.1 with thinking enabled outperforms the older 2 and Pro across all metrics; even without thinking, 2.1 scores higher than both on mask/ink and multi-character tasks. Creators can use this as a signal to prioritize testing tasks involving multiple characters and targeted editing. Elo represents relative preference scores within an evaluation and cannot be directly translated into percentage performance gains; likewise, an AutoRater score of 0.521 does not mean infographics achieve a 52.1% accuracy rate across the board.
Integration: Verifying New Model Identifiers and Platform Quotas
Beyond developer APIs, Nano Banana 2.1 is available across multiple daily touchpoints, including the Gemini app, Google AI Studio, Google Flow, Search AI Mode, and Google Ads.
Within the broader model family, creators and developers can select models according to their task requirements:
- Nano Banana 2.1: Suited for everyday generation and iterative image editing, balancing visual quality, text rendering, and multi-reference editing while maintaining responsive speed and cost efficiency;
- Nano Banana 2 Lite: Focused on maximum throughput and minimum cost, suited for high-volume batch tasks highly sensitive to speed and expense, though not specifically optimized for multi-image reference fusion or multi-turn iterative editing;
- Nano Banana Pro: Designed for the most complex visual tasks demanding deep world knowledge, strict brand consistency, and precise creative control.
If you plan to call the model directly via the Gemini API or Google Cloud platforms, the following engineering boundaries and parameter configurations are critical:
- Context window discrepancy:
- The official model card lists a multimodal processing capability of up to 1 million (1M) tokens for Nano Banana 2.1.
- The current Gemini API and Google Cloud endpoints offer an input quota of 131,072 tokens (approximately 128K) and a maximum output of 32,768 tokens. Structure assets according to the respective platform quota during integration, and do not treat the model card's 1M figure as the active API input limit.
- Parameter support limitations (Google Cloud documentation specification):
- According to official Google Cloud documentation, Nano Banana 2.1 does not support the
seed(random seed),temperature(sampling temperature),topP,topK, andlogprobsparameters; requests on this platform including these parameters will return an error immediately.
- According to official Google Cloud documentation, Nano Banana 2.1 does not support the
- Deprecation notice for legacy models:
- Official API channels have issued a formal deprecation announcement: the legacy
gemini-3.1-flash-image(Nano Banana 2) will be shut down at the end of this month. Pipelines and automated workflows utilizing this legacy identifier must transition togemini-nano-banana-2.1as soon as possible.
- Official API channels have issued a formal deprecation announcement: the legacy
Members can copy or download the full Markdown, and let their AI subscribe and ask.
Found this useful? Leave your email — every new explainer, the moment it's out. Unsubscribe anytime.