边想边说的实时语音大模型:Google 发布 Gemini 3.8 Live 与 Extended Thinking,把实时语音推向多步骤推理
Google 用 Gemini 3.8 Live 覆盖低延迟规模化,用 Extended Thinking 承担多步骤推理。本文直接给出一分钟价格、与上一代的评测结果、七段中英双语演示和 Live API 接入方法。
Google Gemini Audio Team 发布了两款新的实时语音对话模型:Gemini 3.8 Live 面向规模化与成本效率,Gemini 3.8 Live Extended Thinking 面向高复杂度任务与多步骤推理。本文整理两款模型的价格、评测结果、七段演示和接入方法。

一分钟速览
- Google 推出两款实时语音对话模型,分别为主打规模与成本效率的 Gemini 3.8 Live,以及专攻复杂任务与多步推理的 Gemini 3.8 Live Extended Thinking。
- 核心变化在于「边思考边说话」的并行推理机制:模型进行后台工具调用或深度规划时,可以先口头确认请求,并用进度叙述维持交流连续性。
- 刷新多项语音与智能体评测基准,Extended Thinking 夺得端到端语音质量指数第一,并在 τ-Voice 与 Sierra 银行场景测试中领跑任务完成率。
- 官方公布七段演示,覆盖屏幕引导、国际象棋、草图转 React、餐厅预订、品牌设计、Workspace 协作和 Search Live 管道检修。
- 一分钟只监听约 $0.005;如果模型说 30 秒,总计约 $0.014;如果模型说满一分钟,总计约 $0.023。三款 Live 模型价格相同,免费层调用为 $0。
- Gemini 3.8 Live 面向开发者开放 Gemini API 与 Google AI Studio 接入;Extended Thinking 面向企业开启私有预览,并进入 Gemini Live 与部分 Workspace 订阅方案;Google AI 产品生成的音频会嵌入 SynthID 不可感知水印。
双模型分工:轻量化规模落地与高复杂度深度推理
实时语音处理复杂任务时,既要尽快回应,也要在推理和工具调用期间保持对话连续。Google 这次没有用一款模型覆盖所有场景,而是把规模与成本、高复杂度推理分给两个版本。
基础版本 Gemini 3.8 Live 专注于大规模部署的高性价比。它将对话智能与近实时视觉理解、多语言流式切换紧密结合,面向高并发、低延迟的日常助理与检索服务。该模型支持在对话中自动识别并在 97 种语言之间平滑过渡,官方称可精确解析字母数字串,支持增量内容更新与异步函数调用,同时能够在后台执行工具和 API 调用时继续对话。
针对高难度工作流的 Gemini 3.8 Live Extended Thinking 则主打企业级复杂任务执行。它重点强化了多步骤逻辑推理与规划能力,主要面向客户服务、专业排障、多系统协调等需要深度思考的生产环境。两款模型共同构成了从低成本交互到底层复杂业务处理的互补层级。在同一音频产品矩阵中,Gemini 3.5 Transcribe 是支持 85 种以上语言的专用语音转文字模型,官方报告平均词错误率(WER)为流式 4.0%、非流式 2.6%;它并非 3.8 Live 的替代品,而是处于不同系统层级的纯听写转录组件。
| 比较维度 | Gemini 3.8 Live | Gemini 3.8 Live Extended Thinking |
|---|---|---|
| 官方定位 | 面向规模与成本效率 | 面向高复杂度任务 |
| 重点能力 | 流畅对话、视觉理解、97 种语言切换、后台工具调用 | 更强智能、多步骤推理、推理时继续说话与播报进度 |
| 官方演示侧重 | 入职引导、棋局、Search Live 排障 | 草图转组件、复杂预订、Workspace 协作 |
| 当前主要入口 | Gemini API、Google AI Studio、Search Live、企业私有预览 | Gemini Live、部分 Workspace 订阅方案、企业私有预览 |
价格:一分钟到底多少钱
三款模型价格相同。直接按一分钟算:
| 一分钟里发生什么 | 费用 |
|---|---|
| 只保持监听,模型不说话 | 约 $0.005 |
| 模型说 30 秒 | 约 $0.014 |
| 模型说 60 秒 | 约 $0.023 |
计算方法很简单:音频输入监听为 $0.005/分钟,音频输出为 $0.018/分钟,因此模型说 30 秒的输出费用是 $0.009,加上监听费用后共约 $0.014。
| 计费项目 | 付费层单价(美元 / 100 万 token) | 官方时长估算 |
|---|---|---|
| 文本输入 | $0.75 | - |
| 音频输入 | $3.00 | 约 $0.005 / 分钟 |
| 图片 / 视频输入 | $1.00 | 视频约 $0.002 / 分钟 |
| 文本输出(含 thinking tokens) | $4.50 | - |
| 音频输出(含 thinking tokens) | $12.00 | 约 $0.018 / 分钟 |
免费层调用为 $0。上表不含可选的文字转写和 Google Search Grounding 费用。
边想边说与后台执行:怎样减少复杂任务中的长静默
实时语音交互中最破坏交谈直觉的体验,是提出复杂问题后系统长时间没有反馈。Extended Thinking 的关键设计是同时推理和说话:先确认已经接到请求,再在多步骤任务推进时用语音说明进度。
这种实时协同由三项核心交互机制支撑:
第一项是早期口头确认。当用户提出需要检索或计算的请求时,模型会先给出自然的口头反馈(例如「让我想想」「我正在查询这条记录」),通过早期口头确认维持连续交流,避免传统语音交互中令人焦虑的静默。
第二项是实时进度叙述。面对需要调用多个接口或分步骤处理的后台任务,模型并非等待全部结果返回才开口,而是在推演与任务流转过程中通过实时进度叙述向用户同步当前进展,维持连续交流。
第三项是后台执行与对话并行。模型在后台执行工具和 API 调用时继续对话,在后台任务执行过程中维持双向沟通。
评测结果
Google 公布的结果如下:
| 评测基准 | 3.8 Extended Thinking (High) | 3.8 Live | 3.1 Flash Live (High) | 3.1 Flash Live (Minimal) |
|---|---|---|---|---|
| Speech to Speech Index | 82.6% | 76.0% | 71.5% | 63.9% |
| τ-Voice 任务完成率 | 68.6% | 30.1% | 37.7% | 26.2% |
| Sierra τ³-Banking 成功率 | 35.1% | — | 11.3% | — |
| Big Bench Audio 子集每小时成本 | $3.50 | $0.84 | $1.75 | $1.50 |
| Big Bench Audio 得分 | 97.7% | — | — | — |


- Extended Thinking: Speech to Speech Index 82.6%,总分第一;τ-Voice 68.6%;Sierra τ³-Banking 35.1%;Big Bench Audio 97.7%。
- 基础版 3.8 Live: Speech to Speech Index 76.0%;τ-Voice 30.1%;Big Bench Audio 每小时成本 $0.84,为表中最低;Speech Agent Arena 用户偏好排名第二。
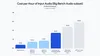
- 与 3.1 High 对比: Extended Thinking 在 Speech to Speech Index、τ-Voice、Sierra τ³-Banking 分别高 11.1、30.9、23.8 个百分点;基础版 3.8 Live 的 Speech to Speech Index 高 4.5 个百分点,τ-Voice 低 7.6 个百分点。
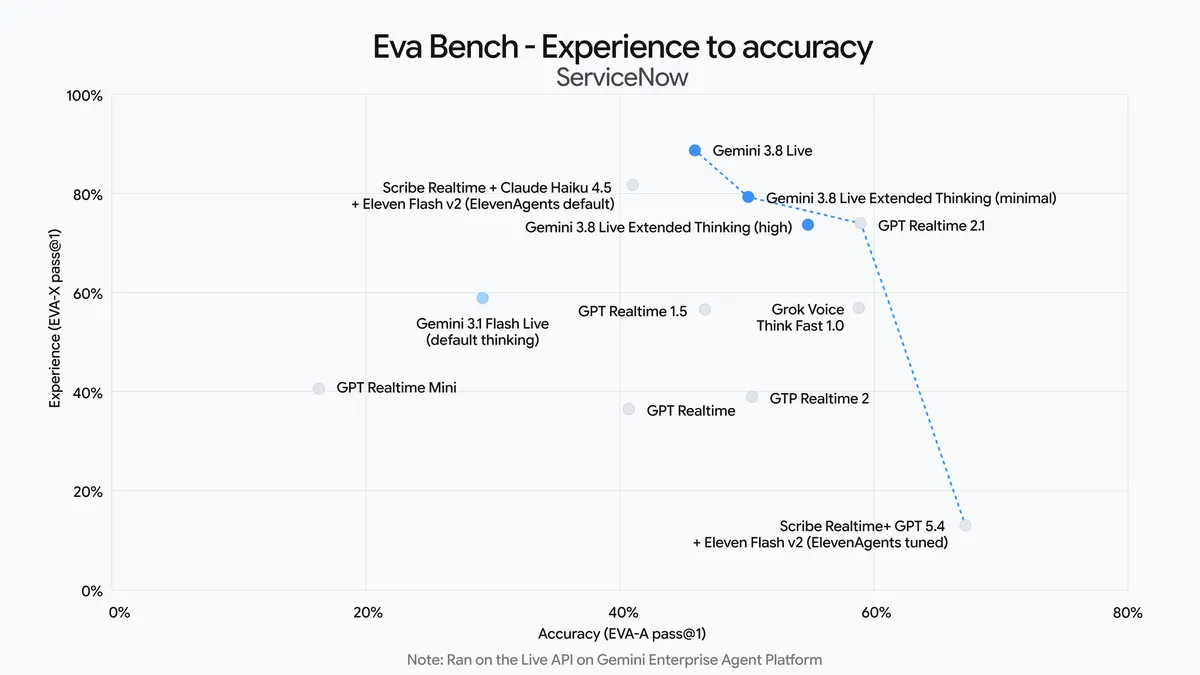
- EVA-Bench: 3.8 系列位于准确率与对话体验的帕累托前沿。

图中的蓝色虚线是 Google 标出的帕累托前沿。
七段官方演示具体展示了什么
官方随技术发布同步公布了七段演示视频,覆盖视觉感知、代码生成、业务打断与跨应用联动。
入职引导助手: 面向新员工 David 的电脑操作引导。模型与用户查看同一个面板,指出侧边栏第二项的人物图标是「个人信息」,确认处于健康与福利页面,并解释 HMO 为健康维护组织。当用户索要信息安全测验答案时,模型拒绝代答并提醒必须由员工自行判断。
国际象棋实时对弈: 模型结合视觉棋盘识别与口语指令完成对局。用户执白依次走 d4、e4、e5、Qf3、Bc4、Qxf7#,Gemini 执黑,最终被将死。
草图实时转 React 组件: 用户在纸上画出手机界面并持续口述修改,模型依次加入占位产品图、文本描述、底部抽屉式菜单和带图标的操作列表,最后切换为玻璃拟态效果。Koray Kavukcuoglu 在 X 上发布的是同一段 71 秒视频,本文保留已经翻译并加入中英双语字幕的版本。
餐厅预订与突发打断处理: 用户预订下周六晚八人的餐桌并询问自带蛋糕规则,途中突然展示一张美食图片,询问是否适合素食者。模型识别出委内瑞拉奶酪卷(Tequeños),回答后返回预订流程,继续收集姓名与电话并完成预订。
拉面馆品牌与营销工具包: 用户要求融合日式传统与布什维克街区感,并采用极简红色。模型在交互画布上生成情绪板,根据语音继续修改城市景观水墨画,随后扩展为品牌规范和标志系统。
Google Workspace 深度协同: 模型在 Gmail 中从邮件提取幼儿园入园物资清单,在 Keep 中整理刷漆步骤和材料清单,在 Docs 中草拟街区聚会方案,并查找已预订的酒店与日期后写入文档。
Search Live 实物管道检修: 用户用手机镜头对准家庭管网,模型根据蓝色手柄阀门指出冷水主入口;读取卡尺后判断这是标称四分之三英寸的铜管,并解释标称内径与实际外径的关系;在给出安装步骤前提醒切断主管的专业门槛和漏水风险。
如何使用:从直接体验到 SDK 接入
不管是无代码直观体验还是工程化开发,Google 提供了从 Web 界面到代码 SDK 的不同接入路径:
1. 普通读者:免配置直接体验
- AI Studio 网页端: 可直接访问 Google AI Studio 的 Live 控制台,在模型下拉菜单中选择
gemini-3.8-live或gemini-3.8-live-extended-thinking,直接利用麦克风与摄像头进行全双工语音与视觉交互。 - 终端产品入口: 普通用户可在 Search Live 中体验 3.8 Live;Gemini Live 以及 Gmail、Docs、Keep 等个人与企业端功能正根据各订阅层级分阶段推送。
2. 开发者:最小可运行 Python 接入示例
开发者可通过官方最新的 google-genai SDK 建立双向 WebSocket 流式会话。
前置准备:
pip install -U google-genai
export GEMINI_API_KEY="your-api-key-here"
最小连接代码:
import asyncio
import os
from google import genai

client = genai.Client(api_key=os.environ["GEMINI_API_KEY"])
model = "gemini-3.8-live"
config = {"response_modalities": ["AUDIO"]}

async def main():
    async with client.aio.live.connect(model=model, config=config) as session:
        print("Session started")

if __name__ == "__main__":
    asyncio.run(main())
3. 选型与迁移关键注意点
- 场景选型:
gemini-3.8-live适用于低延迟日常对话、直接指令与响应速度快的轻量工具;gemini-3.8-live-extended-thinking适用于需要多步规划、诊断排障、调用耗时较长的慢工具,以及需要由模型边思考边用语音遮蔽等待时间的场景。 - 从 3.1 迁移至基础版 3.8: 将模型名称更新为
gemini-3.8-live,并务必移除旧配置中的thinking_level与thinking_config(基础版 3.8 不支持任何思考配置);turnComplete生命周期保持一致。 - Extended Thinking 适配规范:
- 模型 ID 必须指定为
gemini-3.8-live-extended-thinking。 - 函数与工具定义必须显式声明
behavior: NON_BLOCKING。 - 任务生命周期判断:单次语音输出完成仅代表一次语音 turn 结束,会收到
turnComplete: true,并不代表任务整体完成;必须通过读取interaction_status判断整体状态,只有当状态转为IDLE时模型才算真正空闲,若为IN_PROGRESS则表示模型仍在后台思考、执行工具或准备继续回复。 - 思考等级:
thinking_level支持low、medium、high,不支持minimal。
- 模型 ID 必须指定为
- 端侧安全架构: 浏览器端或移动端若需直连 Live API,切勿将长期 API key 硬编码于客户端;必须由后端鉴权服务器签发短期 ephemeral token,长期凭证保留在服务端。
开发者生态与流媒体底座:降低实时全双工门槛
构建一套高可用、低延迟的实时语音对话系统,模型本身的推理只是冰山一角。对于绝大多数应用层开发者而言,管理复杂的实时媒体流基础设施极其繁重。
Google 采取了联合生态伙伴的策略。在 Gemini Live API 开放的同时,Agora、Fishjam、LangChain、LiveKit、Pipecat、Vercel 以及 Vision Agents 等开发者平台与通信云厂商参与合作,由伙伴平台管理复杂的实时媒体流基础设施,使工程团队能够基于 SDK 开发定制语音 Agent。
Google 还列出了 Salesforce、Genspark 和 Lumeris 等合作公司,它们重点肯定了延迟、对话流畅度和工具调用能力。
SynthID 水印与上线范围
为确保透明度与可追溯性,所有 Google AI 产品生成的音频都会嵌入人耳不可感知的 SynthID 水印,使 AI 音频保持可检测。
两款模型的上线推送正在分阶段展开:
Gemini 3.8 Live 面向开发者进入 Gemini API 和 Google AI Studio;企业是 Gemini Enterprise 私有预览并将进入 Customer Experience;普通用户在 Search Live。
Gemini 3.8 Live Extended Thinking 面向企业是私有预览,之后进入 Customer Experience 和 Workspace 商业客户;个人端包括 Gemini Live、Pro 和 Ultra 订阅者的 Workspace Docs,以及所有 Google AI 订阅者的 Gmail 和 Keep。
总结
Gemini 3.8 Live 保持与 3.1 相同价格,适合低延迟、大规模语音应用;Extended Thinking 把多步骤推理、后台工具调用和持续语音反馈放进同一会话,适合复杂客服、排障和跨系统协作。选型很直接:优先成本和速度用 3.8 Live,优先任务完成率与复杂推理用 Extended Thinking。
边想边说的实时语音大模型:双版本分工与后台并行推理
实时语音处理复杂任务时,既要尽快回应,也要在推理和工具调用期间保持对话连续。Google 这次没有用一款模型覆盖所有场景,而是把规模与成本、高复杂度推理分给两个版本。
基础版本 Gemini 3.8 Live 专注于大规模部署的高性价比。它将对话智能与近实时视觉理解、多语言流式切换紧密结合,面向高并发、低延迟的日常助理与检索服务,支持在对话中自动识别并在 97 种语言之间平滑过渡,支持增量内容更新与异步函数调用。
针对高难度工作流的 Gemini 3.8 Live Extended Thinking 则主打企业级复杂任务执行。它重点强化了多步骤逻辑推理与规划能力,主要面向客户服务、专业排障、多系统协调等需要深度思考的生产环境。两款模型共同构成了从低成本交互到底层复杂业务处理的互补层级。
| 比较维度 | Gemini 3.8 Live | 3.8 Live Extended Thinking |
|---|---|---|
| 官方定位 | 面向规模与成本效率 | 面向高复杂度任务与多步推理 |
| 重点能力 | 流畅对话、视觉感知、97 种语言流式切换 | 深度推理、思考时同步说话、播报任务进度 |
| 主要入口 | Gemini API、AI Studio、Search Live | 企业私有预览、Gemini Live、Workspace |
实时语音交互中最破坏交谈直觉的体验,是提出复杂问题后系统长时间没有反馈。Extended Thinking 的关键设计是同时推理和说话:先确认已经接到请求,再在多步骤任务推进时用语音说明进度。
三款模型价格相同。计算方法很简单:音频输入监听为 $0.005/分钟,音频输出为 $0.018/分钟,因此模型说 30 秒的输出费用是 $0.009,加上监听费用后共约 $0.014。
多步推理能力的注入,在多项语音与复杂业务基准上带来了明显提升(以下为官方公布的评测):
接入 Extended Thinking 时,必须理清全双工会话的生命周期状态机:
单次语音输出完成仅代表一次语音 turn 结束,会收到 turnComplete: true,并不代表任务整体完成;必须通过读取 interaction_status 判断整体状态,只有当状态转为 IDLE 时模型才算真正空闲,若为 IN_PROGRESS 则表示模型仍在后台思考、执行工具或准备继续回复。
全双工落地不仅取决于模型本身,更依赖流媒体工程支撑。Google 联合 Agora、LiveKit、Fishjam、Pipecat、LangChain 与 Vercel 提供实时媒体流底座,使工程团队得以基于 SDK 快速构建定制语音 Agent。
同时,所有 Google AI 产品生成的音频都会嵌入人耳不可感知的 SynthID 水印,确保 AI 音频保持可追溯与可检测。
gemini-3.8-live;面对复杂排障、客服多系统协调与跨应用任务编排,选用 gemini-3.8-live-extended-thinking,用边想边说的连续反馈减少复杂任务中的长静默。
Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking
Sep 15, 2026
|
Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking are our most advanced live dialogue models yet. Major upgrades in intelligence and parallel reasoning make them more intuitive to collaborate with and use to execute complex tasks using your voice.
Tom Ouyang
Principal Engineer
Malini Jaganathan
Member of Technical Staff, on behalf of the Gemini Audio Team
Your browser does not support the audio element.
Listen to article
[[duration]] minutes
This content is generated by Google AI. Generative AI is experimental
Today, we’re introducing two new models that bring advancements in near real-time reasoning to more effectively enable voice agents and make conversing with AI feel more intuitive and intelligent.
- Gemini 3.8 Live: Built for scale and cost efficiency, combining conversational intelligence with fluid dialogue and visual grounding.
- Gemini 3.8 Live Extended Thinking: Built for high-complexity tasks, with increased intelligence and multi-step reasoning.
For developers and enterprises, these models deliver the building blocks for reliable, production-ready voice agents. They also make speaking with Gemini across the Gemini app, Google Workspace, and Search more fluid and collaborative — helping you tackle complex tasks using just your voice.
Experience more fluid, intelligent conversations
Gemini 3.8 Live Extended Thinking provides enterprise-grade task completion and intelligence, capturing the #1 overall spot on Artificial Analysis' Speech to Speech Quality Index (82.6), and leads in agentic task completion with 68.6% on τ-Voice and 35.1% on Sierra’s τ-Voice-banking benchmark. It also provides strong reasoning capabilities, scoring 97.7% on Big Bench Audio, while maintaining a highly competitive price point compared to other frontier models.
Gemini 3.8 Live has shown a high preference among users, securing a second place in the Speech Agent Arena. In addition to this performance, it remains highly cost-effective — providing developers and enterprises with a capable and efficient model built for scale.

On ServiceNow’s EVA-Bench, a benchmark for evaluating voice agents, our models push the Pareto Frontier for complex workflows by successfully balancing accuracy with conversational quality.
Note: This was run on the Live API on Gemini Enterprise Agent Platform.
Gemini 3.8 Live processes visual inputs in near real-time, enriching conversations with context for more helpful responses. It automatically detects and transitions between 97 supported languages mid-conversation. It executes tools and API calls in the background while continuing the conversation, so the model can acknowledge requests and keep chatting while tasks finish in the background.
For tasks that require deeper reasoning, 3.8 Live Extended Thinking reasons and speaks simultaneously. It delivers increased intelligence for complex workflows while maintaining an uninterrupted conversational flow — using early verbal cues like “Let me check that…” to acknowledge prompts naturally, and live progress narration to walk users through multi-step background tasks as they progress.
Across Google Workspace and Search, our Live models deliver more intuitive, collaborative experiences — especially when tackling your most complex tasks.
Get step-by-step, real-time troubleshooting help powered by Gemini 3.8 Live — right inside Search Live.
Empowering the developer and enterprise voice ecosystem
By using the Gemini Live API, developer platforms such asAgora,Fishjam, LangChain,LiveKit,Pipecat,Vercel, andVision Agents enable developers to build and deploy high-performance voice-driven interfaces with ease. These platforms manage complex real-time media streaming infrastructure behind the scenes, allowing developers to focus entirely on crafting the user experience.
We’re also partnering with companies like Salesforce, Genspark, and Lumeris who are excited about 3.8 Live and 3.8 Live Extended Thinking, highlighting its impressive latency, fluidity, and tool-calling capabilities.
Ensure transparency with SynthID watermarking
All audio generated by our AI products is watermarked with SynthID. This imperceptible watermark is woven directly into the audio output, ensuring AI-generated content remains detectable to help prevent misinformation. For details on our approach to safety and responsibility, review the model card.
Start using our latest Gemini Audio models:
3.8 Live is rolling out starting today:
- For developers: In the Gemini API and Google AI Studio
- For enterprises: In private preview in Gemini Enterprise and coming soon to Gemini Enterprise for Customer Experience
- For everyone: In Search Live
3.8 Live Extended Thinking is rolling out starting today:
- For developers: In the Gemini API and Google AI Studio
- For enterprises: In private preview in Gemini Enterprise and coming soon to Gemini Enterprise for Customer Experience and Google Workspace business customers
- For everyone: In Gemini Live and for Google AI Pro and Ultra subscribers in Workspace in Docs, and all Google AI subscribers in Gmail and Keep
Get the latest news from Google in your inbox
Sign up for our newsletters with product updates, event information, special offers, and more.
Your information will be used in accordance with Google's privacy policy. You may opt out at any time.