ChatGPT联合发明人 推出一款全新AI模型:System One 不生成文字 专注决策
曾在 OpenAI 联合发明 ChatGPT 与 RLHF 的 Diogo Almeida 推出 System One 模型范式及首款公开模型 Jev:它不生成自由文本,只在代码预定义的结构中返回概率决策。
“System One 模型”与 Jev 是什么?
曾在 OpenAI 联合发明了 ChatGPT 与人类反馈强化学习(RLHF)的 Diogo Almeida,推出了一套完全不同的全新模型类别——“系统一”(System One)模型,并发布了该范式下的首款公开模型 Jev。
现有的主流大模型擅长聊天,却很难在代码里稳定运行自动化。Jev 的核心取舍是放弃逐字生成自由文本,专注输出预定义结构中的类别、分数、概率和置信度。它不是另一个负责聊天或写文章的模型,而是要成为可以嵌入程序控制流的快速决策组件。
“System One”源于丹尼尔·卡尼曼的《思考,快与慢》:系统一代表快速、直觉式的判断,与需要长时间推演的系统二相对。TypeSafe 借这个名字强调,它要解决的是大量需要低延迟反应的分类、评分和路由问题。Jev 的名字则来自经济学中的“杰文斯悖论”(Jevons paradox):蒸汽机效率提高后,煤炭总消耗反而增长。它所表达的产品判断是,当一次智能决策的成本和延迟下降几个数量级,软件对智能判断的需求也会随之增长。
这套模型为什么会出现?因为为人机对话设计的自由文本生成机制,与自动化流水线追求的低延迟、固定接口和可控分支存在明显错位。
过去几年里,大模型在开放式对话和长文本创作上表现亮眼,但在需要确定性逻辑的企业后台代码中,落地进展却常不及预期。主流大模型主要依托 RLHF 对齐,核心目标是输出符合人类评审员偏好的自然语言。为了适配对话,模型必须具备自由生成任意字符串的能力,但这套机制一旦放入代码流水线,就会暴露出三个工程死穴:
响应延迟过高:传统大模型采用自回归逐 token 串行生成。TypeSafe 引用的前沿基准显示,端到端响应时间常在 3 秒到 329 秒 之间。面对屏幕前的人类用户这一耗时尚可接受,但在需要多级级联调用的程序内部,数十秒的等待会迅速累积至不可用。TypeSafe 用“快 100 倍”概括产品卖点;其给出的 Jev 端到端耗时范围是 70ms 至 500ms,实际倍数取决于比较模型与具体任务。
类型系统极其脆弱:大模型原生输出的是字符串,即便提示词要求输出 JSON,本质仍需下游代码反序列化校验。一旦出现多余前缀、格式损坏或意外拒答,底层一次解析异常就会让整条业务调用链崩溃中断。
缺乏可直接依赖的置信度估计:对话模型经由偏好对齐后往往表现得过度自信,自我评估前后矛盾。如果系统无法判断模型何时有十足把握、何时在盲目猜测,下游程序就无法安全地设置自动放行阈值或人工介入兜底。
在人类认知中,系统一并不天然代表可靠;快速直觉同样可能出错。TypeSafe 的技术主张是,当模型剥离自由文本生成、专注类型安全与概率校准后,至少可以从接口结构上消除格式错误与解析异常。至于语义判断是否正确,仍是另一层问题。
它和现有模型有什么区别?
Jev 并不是现有大模型的微调缩小版,而是一套从解码机制到训练范式全部重新构建的独立模型栈。
传统 LLM 架构:
[非结构化输入] ──> [自回归解码器(逐 Token 串行生成)] ──> [自由字符串(需外部校验,存在解析与幻觉风险)]

System One (Jev) 架构:
[非结构化状态] ──> [并行采样器(单次前向硬件加速)] ──> [预定义强类型概率(数学级零类型错误,自带校准置信度)]
| 对照维度 | 两种模型的核心差异 |
|---|---|
| 生成机制 | 对话模型自回归逐 token 串行解码;Jev 使用硬件感知并行采样器(Parallel Sampler),一次计算全部数值输出。 |
| 输出形态 | 对话模型返回自由字符串,仍需解析与校验;Jev 只返回预定义模式(Schema)允许的离散概率或标尺数值,接口层保证类型匹配。 |
| 响应速度 | TypeSafe 引用的前沿对话模型基准为 3–329 秒;Jev 的官方端到端口径为 70–500ms。TypeSafe 宣称“快 100 倍”,四工作流平均里与其准确率相近的 Terra 约慢 25 倍。 |
| 调用价格 | 对话模型通常同时计算输入与输出 token;Jev 早期访问输入为 $0.042/1M token、输出免费。TypeSafe 宣称“便宜 100 倍”,四工作流平均里 Terra 成本约高 76 倍。 |
| 概率与置信度 | TypeSafe 认为 RLHF 模型容易过度自信;Jev 用 RLCD 把“更高置信度对应更高准确率”作为优化目标,但目前没有公开的独立校准曲线。 |
| 适用任务 | 对话模型擅长开放对话、文本创作和复杂推演;Jev 面向数据路由、离散分类、安全护栏与结构化提取,不承担自由文本生成。 |
Jev 最关键的架构取舍在于:彻底放弃自由文本生成。传统大模型采用自回归(Autoregressive)机制,每生成一个新 token 都必须依赖前一个 token,计算在时间维度上高度串行化。而 Jev 在发起查询前由调用端预先定义好输出结构,模型在前向传播中通过硬件感知的并行采样器(Parallel Sampler)单次计算出所有维度的数值输出。TypeSafe 称这使得其端到端响应耗时压缩到了 70ms 至 500ms,在官方口径中实现了相比传统大模型数十倍乃至上百倍的提速。
这一架构重构同时在接口层消除了类型结构错误。传统大模型的输出空间涵盖整套自然语言词表,而 Jev 的输出空间在推理前就已由预定义模式(Schema)完全限定,输出端直接映射为离散类别或标尺的数值概率,因此结构与类型的匹配由接口本身保证。但需要说明的是,这仅能保证输出格式符合预定义结构,并不证明模型的语义判断一定正确。
在训练算法上,现有工业界主要采用两条路线:一条是优化人类阅读偏好的 RLHF,容易导致模型为了迎合人类而过度自信;另一条是面向可验证奖励的强化学习(RLVR),依赖能够被代码单元测试低成本验证的目标(如数学证明或代码编译),但这往往导致模型在缺乏确定性测试用例的真实业务场景中泛化能力不足。
为此,TypeSafe 提出了“面向校准决策的强化学习”(RLCD,Reinforcement Learning for Calibrated Decisions)。RLCD 不考察文字表达是否生动,而是将优化目标定位于“校准决策”(calibrated decisions),官方称其目标是使更高置信度对应更高准确率(higher confidence means higher accuracy),输出具备认识论诚实性的概率分布。不过,官方材料并未公开具体的训练实现细节与独立校准曲线;按其设计设想,面对模糊或模棱两可的边界样本,模型会输出更为平坦分散的概率分布,以便下游工程代码设定阈值进行分支跳转与兜底拦截。
TypeSafe 宣称 Jev 比传统大模型快 100 倍、便宜 100 倍且输出 token 免费。按其公布的早期访问定价,Jev 每百万输入 token 为 0.042 美元(折合每十亿 token 42 美元),输出端确实标为免费;但官方也明确承认,这一定价是否可长期持续仍需时间检验,且百倍降本宣称在官方四工作流实测中也因任务而异(在相近准确率对比中,Terra 成本约高 76 倍)。
它主要用来干什么?成为代码里的“智能判断节点”
在实际工程系统中,完全依靠硬编码规则过于脆弱,而把全流程托付给单体大模型又容易失控。Jev 的核心定位是嵌入常规代码控制流里的“模糊语义判断节点”:代码掌控全局控制流,模型仅负责给出带概率的局部语义裁决。
它最直接的用途,是替代代码中难以穷举规则的“智能 if-else”:对请求进行路由和分类,对风险、满意度或匹配度评分,从非结构化输入中提取受限字段,或者判断某一步是否需要人工介入。低延迟让它也能进入实时交互;低单价适合批量处理大量记录;固定候选和概率输出则使它可以充当其他大模型前后的安全护栏。
在官方 SDK 及开源适配器中,底层语义决策被抽象为三种标准类型原语:
Noul(布尔判定):输入非结构化文本与判定条件,输出该命题成立的概率,用于处理二元判断。
Choice(离散分类):在一组明确定义的候选集合中进行单项选择,返回涵盖所有类别的完整概率分布及综合置信度得分。系统原生最高支持 255 个类别的选择;面对更大范围的候选集时,系统会先并行评分再进行离散抉择。
Score(有序评分):在预设的连续标尺或有序评级(Rubric)上进行打分,返回当前评分值、各档位的离散分布及置信度,适用于严重程度、情感满意度或契合度量化。
以企业日常的员工费用报销审核为例,可以清晰看出两种范式的差异。
在传统大模型方案中,开发者通常将全部业务规范塞进一段长提示词:“每笔报销需附发票凭证;若凭证无法辨认则打回;判断属于餐饮、差旅还是设备采购;餐饮报销超过 75 美元且明细与报销说明不符时需经理审批;其余直接通过。”这种单体提示词要求模型在思维链中一步推导出最终动作,多步逻辑杂糅极易发生推导漂移。
而在 System One 架构下,该业务被拆解为一个由确定性代码和语义原语共同构成的计算图:
                    [收到报销申请与票据]
                             │
                             ▼
         [Q1: Noul] 票据图像或文字是否清晰可读?
                  /                     \
       (否 / 低概率)                     (是 / 高概率)
              /                                 \
       [打回要求重新上传]                  [Q2: Choice] 支出属于何种类型?
                                                │
                                    ┌───────────┼───────────┐
                                    ▼           ▼           ▼
                                  [差旅]      [设备]      [餐饮]
                                    │           │           │
                                    │           │           ▼
                                    │           │    [Python 原生代码]
                                    │           │     金额是否 > $75 ?
                                    │           │      /          \
                                    │           │   (否)          (是)
                                    │           │    │             │
                                    │           │    │             ▼
                                    │           │    │   [Q3: Noul] 发票明细
                                    │           │    │   与申报描述是否吻合?
                                    │           │    │      /            \
                                    │           │    │  (吻合)          (不符)
                                    │           │    │    │                │
                                    ▼           ▼    ▼    ▼                ▼
                                     [ 系统自动核准通过 ]           [ 触发经理二次审批 ]
这种架构将数值比较 amount > 75 直接交还给 Python 运行时处理,杜绝了模型看错数字的风险;票据清晰度与语义匹配度则交由 Noul 和 Choice 节点独立运算。这种模式体现了系统的核心理念:确定性逻辑交给代码,语义理解交给模型。
为了方便开发者将现有 LLM 迁移测试,官方开源了 Python 适配库 system-one-adapter。官方 README 目前仅给出了 Noul 的实际调用示例(Choice 与 Score 的构造参数签名尚未在 README 中完整公开):
from system_one_adapter import SystemOneAdapterClient, Noul

# 初始化客户端,启用结构化输出与概率归一化
client = SystemOneAdapterClient(
    structured_outputs=True,
    llm_answer_mode="probabilities",
    normalize_probabilities=True,
)

# 传入待处理的非结构化上下文与 Noul 布尔问题
response = client.system_one(
    state="本书印刷精美且内容详实,但外包装严重破损导致封面折损。",
    questions={
        "is_positive": Noul(instructions="整体评价是否属于正面好评?"),
    },
    provider="openai",
    model="gpt-4o-mini",
)

# 响应结果自动封装为强类型对象,内含耗时与概率诊断
print(response.answers)
print(response.usage.latency)
能达到什么效果?官方评测与原型演示
为了评估模型在代码集成环境下的表现,TypeSafe 没有采用传统公开学术基准,而是自建了工作流评测。团队认为公开榜单容易诱发针对测试集的优化,也无法直接反映模型作为业务组件嵌入系统时的表现。
官方构建了“工作流基准”(Workflow Evals),在固定的代码计算图内测试模型表现,涵盖四大典型企业场景:
安全事件告警分流(Security Incidents):当终端或服务器触发安全告警时,结合机器历史档案,裁决自动关闭、转交人工分析师还是实施网络隔离。
Agent 轨迹可观测性(Agent Trace Observability):在客服智能体处理完客户工单后,遍历其全量上下文与工具调用日志,判定是否需要人工介入及紧急程度。
供应商发票核验(Invoice Processing):比对发票票面信息、采购订单及入库单据,决定直接放行支付、暂扣核实还是打回退票。
客户服务动态路由(Customer Service):根据用户多轮沟通上下文与账户实时状态,决定智能体下一步的具体执行动作。

由于真实业务语义不存在天然唯一的真值标准,评测基准以两款前沿大模型——GPT-6 Astra 与 Claude Fable 5.1 在开启 High Thinking 深度推理模式下的判定均值,作为事实上的参照共识标签。其余模型均采用默认推理配置参测。
评测得出了一个清晰结论:在这四个样例任务的等权平均里,每个参测模型拆成结构化工作流后,都比让同一模型用一个单体提示词完成全流程更准确、更便宜、更快。这个结论只覆盖这套 harness 与样例任务,不能直接外推到所有业务。
在同等工作流配置下,TypeSafe 官方公布的四项等权平均总览如下。所有准确率都相对于团队自建的“共识标签”,并非外部公认真值;除两款参考模型外,参测模型使用各自提供商的默认推理设置。
| 模型 | 平均准确率 | 每个工作流成本 | 每个工作流耗时 |
|---|---|---|---|
| Jev | 67.8% | $0.0004 | 0.4 秒 |
| Terra | 67.9% | $0.0304 | 10.1 秒 |
| Sol | 74.1% | $0.0836 | 23.3 秒 |
| Opus 5 | 73.1% | $0.1761 | 37.8 秒 |

在官方评测公布的四个工作流等权平均总览中:Jev 的综合准确率为 67.8%,平均耗时 0.4 秒,单次成本为 0.0004 美元;与之准确率相近的 OpenAI Terra 准确率为 67.9%,耗时需 10.1 秒,成本为 0.0304 美元。在此项可直接复算的总览对比中:在相近准确率下,Terra 相比 Jev 耗时约 25 倍(10.1s 对比 0.4s),成本约 76 倍($0.0304 对比 $0.0004)。
除上述四个工作流的等权平均总览外,官方评测页面后续还依次列出了四个单项工作流:安全事件(Security Incidents)、智能体轨迹可观测性(Agent Trace Observability)、发票核验(Invoice Processing)以及客户服务(Customer Service)。官方数据显示,Jev 在大幅削减时延与成本的同时,保持了与主流前沿大模型相当的决策质量。
两个原型演示:高频决策与受限候选选择
依托低延迟与强类型特性,官方展示了几个传统大模型难以胜任的原型场景:
Doom 实时控制:在官方演示中,工程师将经典游戏 Doom 运行中的实时状态提取为结构化数据并输入 Jev,模型以每秒 10 次(10 queries/s)的频率输出下一步动作;TypeSafe 称驱动该游戏智能体每小时的总体调用开销约 7 美元。
维基竞速挑战(Wikiracing):规则是从一个维基百科词条出发,仅通过点击词条内部超链接跳转到达指定词条。每一步操作往往面临大量候选链接。传统生成式模型在自由输出文本时可能伪造页面中不存在的链接;而在 Jev 中,由于候选集合受到严格的类型与模式约束(仅在给定的合法候选链接集合内打分选择),因此结构上杜绝了生成非法链接的情况。官方称其以更少的步数完成了路径寻找,但这源于候选集合受类型约束的结构保障,并不代表在所有语义层面零幻觉。
现在的局限性是什么?
尽管官方基准表现优异,但在系统选型与实际落地前,仍需审慎评估其背后的技术假设与边界条件。 三层“可靠性”的工程边界:在系统选型中,必须清晰区分三个层面的“可靠性”,避免将局部机制推论为全流程正确:
- Schema 与类型安全(Type Safety):Jev 的零类型错误源于输出空间直接绑定预定义模式(Schema),输出端直接映射为离散类别或标尺数值,接口在结构上杜绝了 JSON 损坏或格式漂移;这是目前唯一能够从机制上保证的结构可靠性。
- 概率校准(Probability Calibration):RLCD 以“更高置信度对应更高准确率”为训练优化目标,旨在让模型输出诚实反映把握度的概率分布;但这属于模型训练目标与官方主张,目前没有公开充分的训练细节与独立校准曲线,不可等同于已验证的绝对事实。
- 业务语义正确性(Semantic Correctness):无论类型格式如何安全、置信度如何标定,模型推断本质上仍属统计概率,并不保证业务逻辑判定绝对正确。在生产落地中,仍必须由用户自建针对业务的评测基准(eval)、配置严谨的决策阈值与人工介入兜底机制。

基准与环境考量:官方公布的亚秒级时延主要测试于美西服务机房与同地域开发环境,对于跨国或长距离调用的团队而言,物理网络往返延迟(RTT)会在总耗时中占据明显份额。此外,官方坦言超低定价策略能否长期持续仍需商业检验;以 Astra 与 Fable 5.1 作为评估参照系,也在客观上偏向了特定模型家族的逻辑偏好。
架构适用边界:Jev 放弃的是自由字符串生成能力,因此不能直接承担自由对话、开放式问答或文本创作。它更适合作为高吞吐的语义路由网关、实时交互逻辑以及确定性系统内的特征提取器。
对于系统架构师而言,Jev 的价值不是取代传统大模型,而是促成了智能架构的分层演进:极速、廉价的系统一模型负责处理绝大部分确定性的数据流转与边界防御,而将昂贵、擅长深思的长思维链大模型保留在最关键、最需要推演的专家级节点上。
常见问题解答
Jev 是否只是把现有大模型做了轻量化剪枝或蒸馏?
不是。Jev 既不是轻量化小模型,也不是传统意义上的自回归大语言模型。它的输出空间、采样器和训练算法全部重构,专注于分类与概率校准任务,因此脱离了传统 LLM 的帕累托前沿曲线。
为什么官方不公布通用公开学术基准(如 MMLU)的成绩?
官方认为通用公开榜单容易导致提示词过拟合,无法反映模型作为函数组件嵌入生产代码时的真实表现。团队主张用户针对自身业务工作流构建评测,直接检验类型稳定性与校准精度。
Jev 的训练数据来自哪里?
TypeSafe 称数据由内部自行制作,并表示不会用客户传入数据训练。
ChatGPT联合发明人 推出一款全新AI模型:System One 不生成文字 专注决策
在大模型落地自动化系统的进程中,工程团队常常陷入两难:完全依靠硬编码规则过于僵化脆弱,而将业务全流程托付给单体生成式大模型又极易失控。
因为为人机对话设计的自由文本生成机制,与自动化流水线追求的低延迟、固定接口和可控分支存在明显错位。
传统 LLM 在后台流水线中的三大工程死穴:
1. 延迟过高:自回归逐 token 串行生成导致 3–329 秒等待,多级调用链瞬间瘫痪;
2. 类型脆弱:自然语言转 JSON 存在幻觉与格式漂移风险,反序列化异常会使整条流水线崩溃中断;
3. 过度自信:RLHF 迎合人类偏好导致置信度失真,下游代码无法设定可信的分流阈值。
Jev 并非现有大模型的微调缩小版,而是一套从硬件采样到接口类型全部重新构建的独立模型栈。
核心机制:单次前向并行采样与职责彻底切分
Jev 的核心取舍是放弃逐字生成自由文本,专注输出预定义结构中的类别、分数、概率和置信度。接口在推理前就已由预定义模式完全限定,直接映射为数值概率,从数学结构上消除了类型错误。
[收到报销申请与票据]
        │
        ▼
[Q1: Noul] 票据是否清晰可读? ──(否/低概率)──> [打回重新上传]
        │ (是/高概率)
        ▼
[Q2: Choice] 支出属于何种类型? ──[差旅 / 设备]──> [系统核准通过]
        │ [餐饮]
        ▼
[Python原生代码] 金额是否 > $75 ? ──(否)──> [系统核准通过]
        │ (是)
        ▼
[Q3: Noul] 发票明细与申报是否吻合? ──(吻合)──> [系统核准通过]
        │ (不符)
        ▼
[触发人工经理二次审批]
语义原语:代码如何调用智能 if-else?
它最直接的用途,是替代代码中难以穷举规则的“智能 if-else”:对请求进行路由和分类,对风险、满意度或匹配度评分,从非结构化输入中提取受限字段,或者判断某一步是否需要人工介入。
布尔命题判定。输入上下文与条件,直接输出成立概率。适用于状态可读性、合规放行等二元分支判断。
离散多项分类。在给定有限候选集(原生最高 255 类)中输出完整概率分布及置信度。杜绝幻觉选项。
有序等级打分。在预设标尺或评级标准上输出数值及置信度分布。适用于严重程度、情感满意度量化。
在 Python 中,通过 system-one-adapter 调用 Noul(instructions="..."),响应直接封装为强类型属性,自带耗时与概率诊断,无需任何外部正则表达式或 JSON 解析保护层。
官方评测:工作流基准与成本前沿
TypeSafe 自建了包含安全事件分流、智能体轨迹可观测性、发票核验与客户服务四大真实场景的 Workflow Evals,以开启深度推理的 GPT-6 Astra 与 Claude Fable 5.1 均值作为基准共识标签进行等权测试。
评测证实:在这四个场景中,将任务拆解为结构化计算图的工作流模式,在准确率、耗时和成本上普遍优于单体长提示词。依托亚秒级低延迟与受限候选特性,官方展示了每秒 10 次动作决策的 Doom 游戏控制(约 $7/小时),以及从结构上杜绝生成伪造超链接的维基竞速(Wikiracing)原型。
工程理性:必须区分的三层“可靠性”边界
必须清晰区分三个层面的“可靠性”,避免将局部机制推论为全流程正确:
Jev 的零类型错误源于输出空间直接绑定预定义模式(Schema),输出端直接映射为离散类别或标尺数值,接口在结构上杜绝了 JSON 损坏或格式漂移。
RLCD 旨在使更高置信度对应更高准确率,输出具备认识论诚实性的概率分布。但目前官方尚未公布独立校准曲线,不可盲目等同于已验证真理。
无论类型格式如何安全、置信度如何标定,模型推断本质上仍属统计概率,并不保证业务逻辑判定绝对正确。生产系统仍需自建评测基准与人工介入兜底。
系统架构师的技术启示:Jev 的价值不是全盘替代生成式大模型,而是推动了智能软件的分层演进——极速、廉价的系统一模型负责处理绝大多数确定性的流转分发、前置提取与边界防御,而将昂贵、擅长深思的长思维链大模型保留在最关键、最需要推演的专家级节点上。
Introducing System One Models & Jev
Published: Sep 15, 2026 Author: Diogo Almeida, founder, TypeSafe Source: https://typesafe.ai/blog/introducing-system-one-models-and-jev
Diogo Almeida, founder, TypeSafe
Models have been superhuman at chat for years, so where is all the automation?
This has been my driving question for the last four years. At OpenAI, I helped build the methods that made language models useful at following instructions and talking with people. That work ended up as the research behind ChatGPT. At the time, I thought maybe chat models would lead to AGI, but despite the hype it became obvious to me that there was something really big missing.
After two years in stealth, countless technical challenges, and research breakthroughs… I am beyond excited to announce that today, TypeSafe AI is releasing our first System One Model: a new class of frontier models built to make fast, structured decisions that software can use directly.
We built a new stack entirely focused on automation: with a new model architecture, parallel sampler for maximum efficiency, and training method we call Reinforcement Learning for Calibrated Decisions (RLCD).
Our first public model is Jev, available today in early access. Jev achieves similar levels of intelligence on System One tasks compared to existing LLMs, while being two orders of magnitude faster and more efficient. While Jev gives up string generation, it’s optimized for structured outputs and can’t hallucinate.
Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.
Extraordinary claims require extraordinary evidence so see below for the receipts. 💅
Frontiers, Old and New
| Existing LLMs | System One + Jev | |
|---|---|---|
| Optimized with | Reinforcement Learning with Human Feedback (RLHF) / Reinforcement Learning with Verifiable Rewards (RLVR) | Reinforcement Learning for Calibrated Decisions (RLCD) |
| Optimizes for | Human preference: writeups and chat responses that human raters prefer. Verifiable rewards: outputs that can be programmatically verified. | Calibrated decisions: answers with epistemically honest probabilities on System One tasks. |
| Inputs | Unstructured data (e.g. text) with an emphasis on sequential messages. | Unstructured data (e.g. text) with an emphasis on structured program state. |
| Outputs | Strings / generated text. Strings are flexible and can be anything: chat responses, code, hallucinations, refusals, or even type-safe structured values. To be used by software, responses need to be parsed + validated. There is also always some risk that the AI goes off the rails. | Type-safe structured values. Possible outputs and structure are defined in advance. The model never makes type errors. All answers are accompanied with calibrated probabilities and confidence scores. |
| Sampling | Sequential. Generates one token at a time, each conditioned on the last. | Parallel. Generates all outputs in a single query. Incredibly efficient and hardware-aware. |
| Cost | Input tokens: from $0.20 to $10 / MTok. Output tokens: ~5x more expensive than input tokens. | Input tokens: $0.042 / MTok ($42 per billion tokens). Output tokens: FREE (too cheap to meter). |
| Speed | End-to-end response time is 3 to 329 secondsfor frontier models. Fast enough for interfacing with humans, but a big bottleneck when integrated in code. | End-to-end response time is 70ms-500ms for TypeSafe. This can range from 40x-200x faster for the same levels of frontier intelligence for System One shaped queries. |
| Confidence | Even if prompted for a confidence estimate, models tend to be overconfident and inconsistent. If a model can do a task 95% of the time but doesn’t say when it’s in the 5%, it can’t automate that task. | Always communicates confidence and uncertainty with every output. Calibrated: higher confidence means higher accuracy. More consistent: returns similar answers for similar inputs. |
| Use cases | Human-in-the-loop tasks (chatbots, copilots, coding agents). General and powerful, but requires human oversight because their freedom also means they might go off the rails. Verifiable problems (math proofs, kernel optimization). When correctness can be checked cheaply and automatically, LLMs can generate, test, and iterate until they find something that works. Demos. The flexibility of strings allows it to be incredible for quickly making prototypes that only work sometimes. | AI-Powered Workflows / smart if-statements. Structured outputs slot into ordinary software as fuzzy decision rules: classify, route, score, extract, or branch where hand-written logic is too brittle. The surrounding code constrains their freedom, making them easier to compose into reliable systems. Map-reducing over big data. Turn petabytes of data into features and insights. Real-time applications. 100ms speeds means you can use AI in your applications where UX is critical. Verify everything. Score, judge, verify, guardrail, and detect jailbreaks of LLM prompts, reasoning traces, and/or outputs. |
Evidence / Technical Results
We love skeptics, and are skeptics ourselves.
There are some claims you can easily verify:
- Speed per call: We truly are that fast, though our published evals are generally run from our laptops on the West Coast (this is where our service is currently based).
- Cost per call: We make our pricing transparent. We can’t prove it isn’t subsidized; we’ll need the long-term to prove the sustainability of our pricing (which we expect to go down, not up).
- No type errors: This would be an easy thing to falsify with just a single counter-example, but it is mathematically impossible.
For our bolder claims, we want to provide as much nuance as we can.
Side-by-side demonstration
Our side-by-side demo shows a key difference between our models and LLMs: Jev outputs all probabilities in parallel instead of autoregressively generating by token. Strings are extremely powerful and general, but costly. “Giving up” strings actually gives us a lot of superpowers!
Nuance
- For people with early access to TypeSafe, here is the actual query.
- The query is highly simplified and
questionswere chosen to have descriptive, human-readable keys so that the output on the screen is understandable. - The
stateis also a short, dense, and detailed paragraph, to emphasize the difference in sampling methodology. The relatively shorter input paints our model in an advantageous light. - For the keen eyed, for the recorded run, the only disagreement with GPT-5.6 Terra is on “Churn likelihood level”. The actual answer seems genuinely ambiguous to us.
- We used GPT-5.6 Terra with default reasoning for this example, because we’ve found it to be the most comparable at intelligence to Jev on average.
- Fun fact: a similar demo was what convinced us to go all-in in the direction of System One Models!
Workflow evals
We made a new type of evaluation to measure how well AI works within code. We don’t optimize for a ground truth classification orand allow the harness and model to change (potentially allowing for overfitting via harness engineering). Instead, we assume there is a correct compute graph (a “workflow” represented in code) and use the predictions of the largest, smartest, and most expensive external models as reference probabilities.
Rephrased: every model gets the same workflow. We test how they compare to the average of the smartest models (in this case, Astra and Fable).
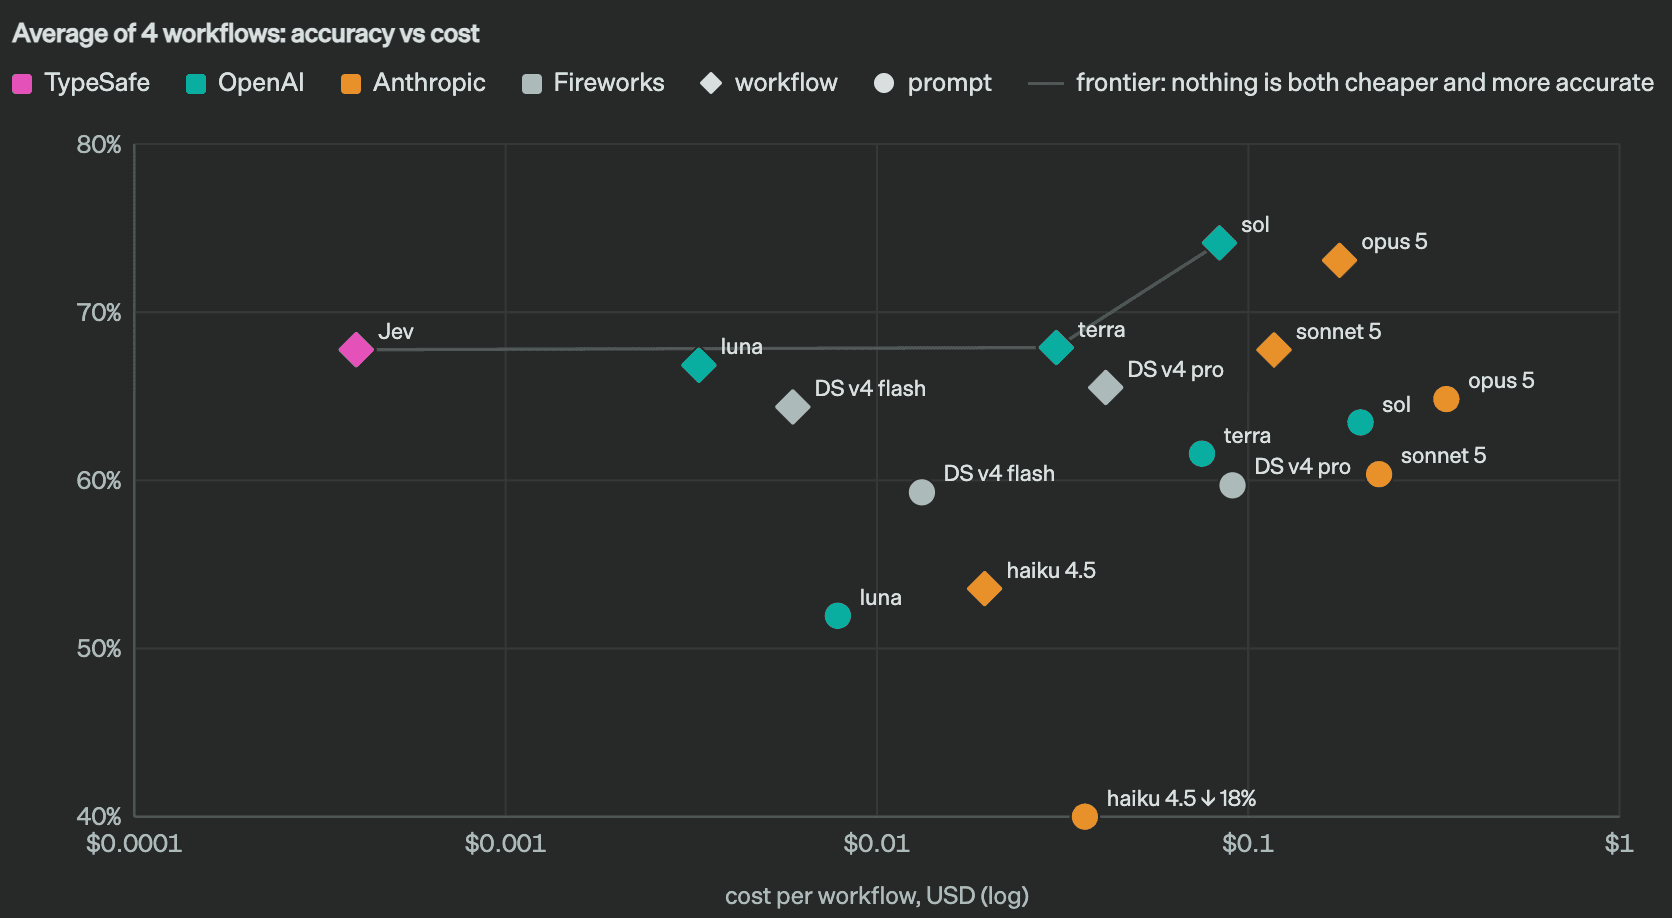
Jev is off the charts – owning the Pareto frontier for almost 2 orders of magnitude. We also compare to models with a generated prompt doing all the logic in their chain-of-thought, but this tends to do significantly worse than using the workflow itself.
Note that the calls here are significantly more complex than the side-by-side demonstration above. That’s because they’re more representative of the types of production workloads needed for true business automation. Below is the simplest of the 4 workflows we’re publishing:
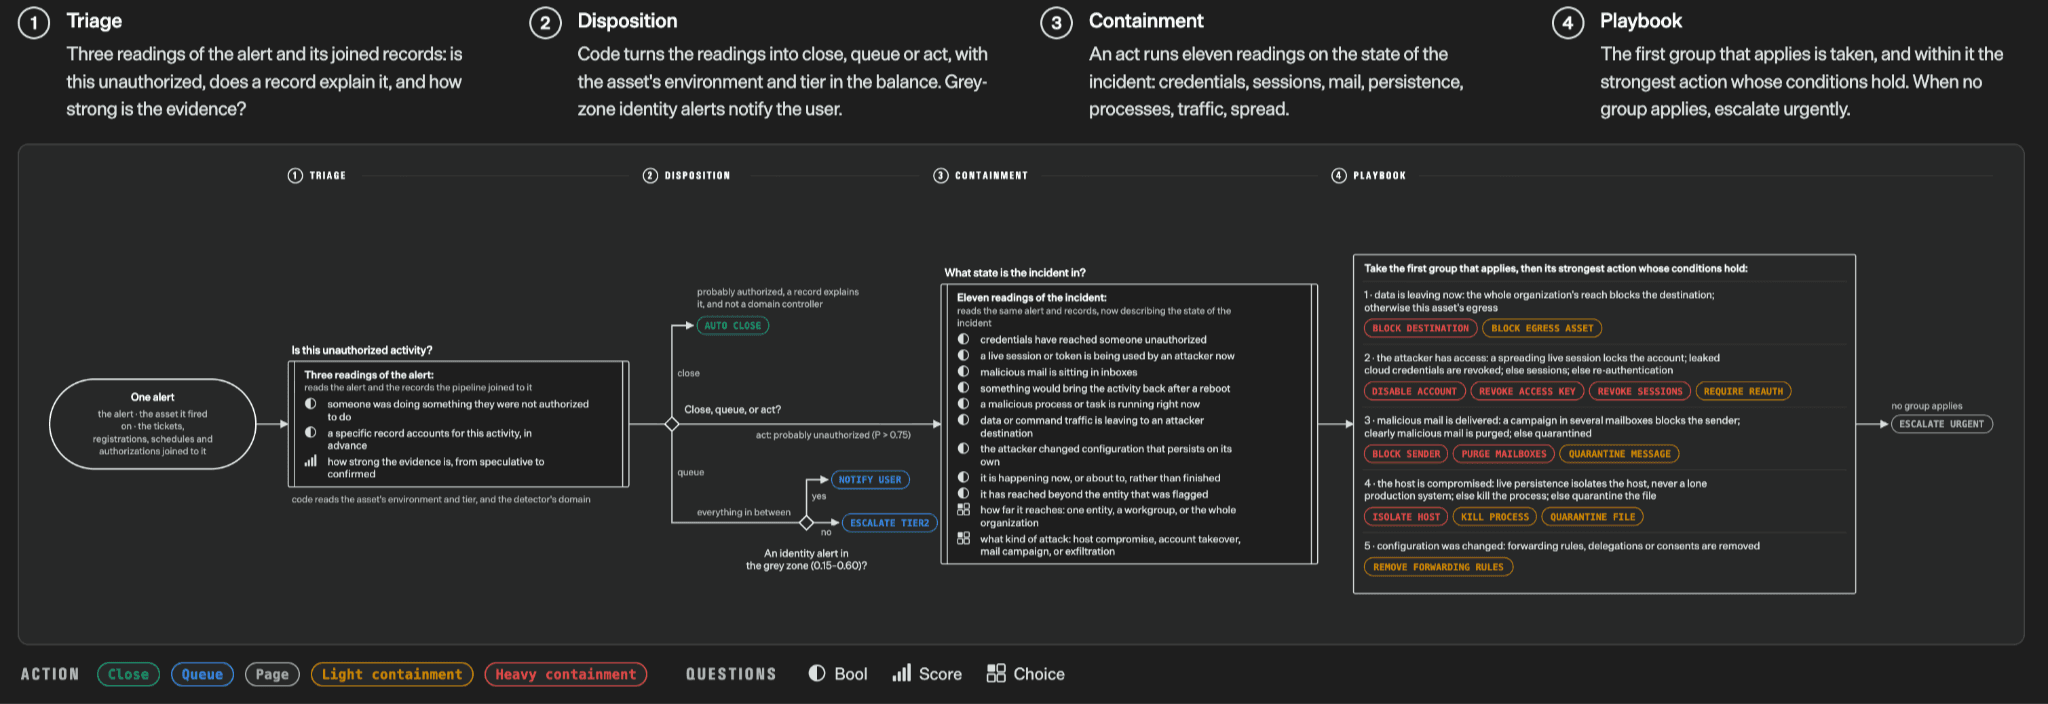
The most reliable real-world workflows tend to have many independent, decomposed questions, with fine-grained behavior that’s dependent on probabilities instead of discrete decisions. The end result is discrete branching, but how we get to a final answer involves a lot of domain-specific engineering that needs to be done highly consistently.
See our workflow evals site for all the details: examples, disagreements, full queries, and each workflow.
Nuance
- This is where the claims of 193.6x faster, 444.6x cheaper on our home page comes from, and we expect that these are on the higher end of real world gains.
- These content of these workflows were not deliberately chosen nor constructed to make our model look good, and are not in our training distribution. However, they were made by individuals on our model capabilities team, so some bias could exist.
- We use the average of GPT-6 Astra and Fable 5.1 as the reference answer, which biases answers towards OpenAI and Anthropic’s models. We likely underestimate the relative performance of our model and DeepSeek’s models.
- The LLMs use our System One LLM wrapper, which constrains LLMs to output structured decisions compatible with our API. We have found this to be the most accurate way to get decisions from LLMs, but this tends to be slower and more expensive than giving decisions without probabilities.
Hallucination and Type-safety

Hallucination and type-safety are intrinsically related, and we think the latter is table stakes for automation. Having a hallucinated tool call is inconvenient in an agent, but is an absolute deal-breaker if it’s part of a system with latency guarantees or it’s buried several layers deep in a dependency chain. Existing models, no matter how smart, still hallucinate and have type errors.
Nuance
- The numbers for LLMs are from OpenRouter i.e., there almost certainly is bias here: more complex queries might be routed to better models.
- Our number is not empirical. Schema matching is guaranteed, thus we can confidently add 0% into the plots.
Fun Demos
Perhaps the most exciting part of our work is enabling new use cases. We have a lot more to show you, but here are a couple of the team’s favorites:
Doom
We love how this doomo doomonstrates real-time intelligence and what can be doone with code + AI. The engineer behind it was worried about making 10 queries a second (which ends up costing ~$7/hour), but the rest of us agreed that was lower than expected! This is so fun we intend to not only release an in-depth walkthrough, but also host some events to hack on this.
Nuance
- The demo is on structured state as a data structure with text, not on images (yet…)
- A non-AI doom bot could play better, but we wanted a bot that was reactive to different representations of game state, and most importantly… following instructions was cool as heck!
Wikiracing
The objective of the game is to start on one Wikipedia page and reach a specific other Wikipedia page using only links you come across while traversing. Each step can mean choosing between hundreds to thousands of links! It’s a great playground for demonstrating not just intelligence-per-second, but also the compounding benefits of not hallucinating with high-cardinality choices.
Nuance
- As far as we know, it was completely random that both the 2nd and 3rd challenges started with “Rubber Duck.” The author only noticed when the team pointed it out.
- Our speedups here tend to be a lot less than in previous demos. That’s because this is against the non-reasoning modes of the models (except Astra which was set to the lowest reasoning setting). This is also why Jev tended to finish in fewer steps (a sign of greater intelligence). This was to make the demo more bearable to watch. The LLMs look much worse at this task than with reasoning enabled.
- Jev supports a cardinality up to 255. For the higher cardinality choices, we do a 2 stage-system of scoring independently then making an explicit choice, hence the occassional slowdown.
What’s next
We’re still in Jev’s early days. We have a lot more in the pipeline and are so excited to keep on shipping 🔥.
Today, we are opening early access and bringing developers off the waitlist as quickly as we can. We want to hear which decisions you need to automate, where Jev works, and where it falls short. Tell us what sci-fi you want to build!!
We started TypeSafe because we believe that AI needs an interface software could depend on. We can't wait to see new use cases continuously diffuse through the community and economy.
We Give A FAQ
Where do the names “System One Models” and “Jev” come from?
We were inspired by Daniel Kahneman, Thinking, Fast and Slow. The model class name draws on the distinction between fast, intuitive System 1 thinking and slow, deliberate System 2 reasoning.
“System 1 thinking” has also implied error-prone. For reasons we will get into in the future, we believe System One Models can be made more reliable than its alternatives.
We named Jev after William Stanley Jevons. We expect machine intelligence to follow a similar path to coal, after steam-engine efficiency led to an increase in demand. Every order of magnitude drop in the cost of intelligence unlocks orders of magnitude more use cases.
Why was a new training algorithm needed?
What use cases is Jev good for?
Is Jev just a smaller LLM?
How does Jev perform against public benchmarks?
Where does our training data come from?
These are results are kinda crazy - how is it possible?
FAQ answers present in the page data but collapsed in the initial HTML
Why was a new training algorithm needed?
Every lab optimizes for the same task during Reinforcement Learning with Human Feedback (RLHF): produce the text that a human rater prefers. That was the right task for a chat product, but it is the wrong task for automation. This is what we call the bitterest lesson: optimizing for the right task matters more than data, compute, or algorithms.
RLVR is great for tasks with simple programmatic verification, but most real-world judgement tasks don’t fit into that shape. This tends to cause spikey / non-robust intelligence.
What use cases is Jev good for?
We’ve found diverse use cases for Jev across industries. We outline some in our docs, and are excited to see what else developers build.
Is Jev just a smaller LLM?
Jev is neither small nor an LLM, hence being off the intelligence Pareto curve.
How does Jev perform against public benchmarks?
We deliberately chose not to publish performance against public benchmarks. In fact, we plan to only have one-off evals when we make product updates.
Given that we are opening up a new frontier for models, we’re pushing for more useful best practices:
- Put no weight on public benchmarks.
- Encourage users to create their own evals for their use cases (System One tasks are much easier to evaluate).
- Disclose the nuance in your evals.
- De-emphasizing benchmarks even when you’re ahead.
Where does our training data come from?
TypeSafe is primarily a data research lab, which is how the biggest results in AI get made. We make all the data ourselves. We wouldn’t train on your data even if you asked us to (no offense). We do some pretty sophisticated stuff, but if you want to find out more, we’d have to hire you.
These results are kind of crazy — how is it possible?
The short answer is that you get what you optimize for. LLMs optimized for being incredible chatbots and copilots, which made them superhuman at those humans-in-the-loop tasks. We’re optimizing for the System One interface.