a16z 深度解读:SaaS 巨头的反扑战,与垂直 AI 的终极护城河
巨头守得住底座,却吞不下真实业务。从 Claudeforce 到 4 级 Agent 阶梯,为什么把守数据底座的巨头依然赢不下最终交付?
- 企业软件巨头正从检索型聊天机器人全面升级为流程与策略智能体,并与通用模型厂商联合卡位底层数据与统一前门。
- a16z 提出 Agent 四级阶梯(检索、流程、策略、负责人),指出巨头判断力局限于局部记录,而真实工作天然跨系统与组织边界。
- 通用模型记忆无法替代专业学习,垂直 AI 通过工程化制造专业课程与生产环境纠错,能高效沉淀行业标准与机构规则。
- 在高频发生、依赖专家权衡且具备强学习闭环的场景中,能够端到端交付任务本身的垂直 AI 公司依然拥有不可替代的壁垒。
生成式 AI 爆发初期,企业软件界曾流行一种乐观预期:大模型将迅速瓦解传统 SaaS 帝国,灵活轻巧的 AI 原生应用会取代陈旧的业务数据底座(即行业通常所说的记录系统 System of Record,如 CRM、ERP 等核心业务数据库)。但在实际演进中,企业软件巨头非但没有被颠覆,反而与通用大模型厂商结盟发起了全面反击。
Salesforce 与 Anthropic 联合推出“Claudeforce”,员工直接在 Claude 对话框内就能调取和修改 CRM 数据,无需打开 Salesforce 后台;Docusign、Atlassian、Klaviyo 等老牌软件也纷纷上线能直接批合同、派工单、发营销活动的智能体。
面对通用模型抢占统一前门、软件巨头把守底层数据的两头挤压,垂直 AI(Vertical AI)创业公司究竟还能退向何处?
硅谷风投 a16z 合伙人 Seema Amble 分析指出:企业记录系统并没有被边缘化,巨头们正在从早期的聊天机器人升级为具备工作流操作与策略判断能力的智能体;但客户真正要完成的工作,本质上远大于系统里的单据记录(The job is bigger than the record)。巨头守得住单据,却占不满真实任务;垂直 AI 的壁垒不在于通用包装,而在于把整项工作端到端交付。
攻守逆转:为什么软件巨头守住了底座,大模型反倒成了“前台”?
目前市场上支持传统企业软件的看多逻辑非常直接:AI 非但不会削弱老牌 SaaS 的业务数据底座,反而会让这些底层数据变得比以往任何时候都更加关键。原因在于,现在的企业客户理论上可以直接把 CRM、ERP 或 HR 软件底层的数据管道接入 Claude 或 Codex,从而绕过所有中间层的轻量 AI 工具。
当智能体能够通过既有系统承揽更多具体工作时,这些老牌系统独占的数据资产、权限体系与 API 接口,价值便随之水涨船高。由此推导出的乐观结论是:一个成熟的业务数据底座,搭配一个顶尖的通用大模型(或巨头自研的专用智能体),就已经足以解决企业客户的绝大部分问题。
Salesforce 与 Anthropic 联合推出的 Claudeforce 便是这种模式的标杆样本。用户直接在 Claude 聊天界面内调用和操作 Salesforce CRM,前端交互界面与底层数据底座彻底解耦:Claude 成为企业员工推进业务的统一前门,而 Salesforce 依然牢牢掌控着底层客户数据、权限审计与业务流转。
更深层的变化在于:现有软件巨头正在以惊人的速度推进自身产品的 Agent 化。在 2024 至 2025 年间,多数巨头的 AI 策略还停留在“给老系统硬贴一个聊天机器人(slap on a chatbot)”的粗浅阶段;而到了 2026 年,巨头们的产品正全面转向具备执行能力的智能体:
| 巨头产品 | 核心智能体功能 | 2025 阶段(侧边栏问答) | 2026 演进(流程/策略智能体) |
|---|---|---|---|
| Docusign Iris | 商业合同审查与红线标记 | 仅在侧边栏回答合同条款内容 | 依据企业法务手册自主审查合同并标记红线 |
| Atlassian Rovo | 技术工单分派与自动化执行 | 检索 Jira 文档与工单历史 | 自动分派故障工单、触发排查流并回填处理结果 |
| Klaviyo Composer | 营销活动策划与效果归因 | 生成营销邮件文本初稿 | 端到端编排跨渠道营销活动并实时调整投放策略 |
| Procore | 施工合规与工程变更单审查 | 查找施工规范与图纸问答 | 自动审查工程变更单、比对图纸合规性并标注风险 |
这些老牌产品不再只满足于被动存储业务数据,而是直接将触角伸向了工作流操作本身。如果通用大模型能做前门,软件巨头能管执行,AI 原生初创团队的生存空间究竟在哪里?答案在于聚焦(Focus)。垂直 AI 公司绝不能停留在通用的提示词包装上,而必须将精力集中在某一项特定的复杂工作上,在跨系统协同深度、特定场景上下文以及衡量交付质量的学习闭环上,做到比巨头系统或通用模型更懂真实业务。
四级能力标尺:从单点检索到规则裁决,巨头能走到哪一步?
要厘清软件巨头的防线究竟推到了哪里、垂直创作者的机会又卡在何处,首先需要建立一套评估企业级智能体的统一标尺。a16z 将企业级 Agent 划分为四个层级,各层级以其所需的自主权(Autonomy)与专业判断力(Judgment)为严格分界:

Agent 四级自主与判断阶梯(The Agent Hierarchy)
企业级智能体的演化分水岭:从读取记录到规则内裁决,为什么最终责任仍在人类手中?
点击各层级切换按钮查看详细职责、能力依赖与技术分水岭。
检索助手 (Retrieval)
检索系统信息、提炼文档、执行基础分析并起草初稿
数据访问权限 + 检索上下文(Data access + context)
人类依然是实际推进工作的唯一责任主体
流程智能体 (Process)
更新业务记录、调用既定工具、路由审批流、执行预设工作步骤
工具权限 + 访问许可 + 工作流状态(Tools + permissions + workflow state)
判断力仅限于在既定规则中选择下一步动作
策略智能体 (Policy)
将企业的业务手册(Playbooks)、判例与风险阈值应用到含糊暧昧的真实个案中
代码化策略 + 评测集 + 持续学习闭环(Codified policy + evals + learning loop)
调用组织已经明确表达过的专业判断(如 Docusign Iris 审查合同条款)
负责人智能体 (Principal)
在高度不确定下做开放式权衡,平衡商业战略、风险承受力与多方利益分配
宏观目标 + 最终授权 + 真实责任追究(Objectives + authority + accountability)
目标本身可能充满争议与博弈;目前依然牢固掌握在人类手中
这四个层级的定义与能力依赖具有严格的递进关系:
- 检索助手(Retrieval Assistants · READS):主要职责是查询信息、总结文档、回答问题并起草初稿。它们依赖数据访问权限与上下文检索。在这一层级,智能体只负责提供信息,人类员工依然是推动实际工作前进的唯一主体。
- 流程智能体(Process Agents · DOES):主要职责是执行确定性的规则任务,如在系统中更新记录、触发审批流转、分派标准工单。它们依赖工具调用权限与工作流状态管理。其判断力主要体现在“在预先设定的有限路径中选择下一步操作”。
- 策略智能体(Policy Agents · DECIDES WITHIN RULES):主要职责是将组织内部的业务手册(Playbooks)、历史判例与风险阈值应用到模糊复杂的真实个案中。它们依赖代码化的政策规则、完备的评测集以及持续学习循环。在这一层级,智能体开始调用组织此前明确表达过的专业判断力。
- 负责人智能体(Principal Agents · DECIDES WHAT TO DO):主要职责是面对不确定性进行开放式的宏观商业权衡,在发展战略、风险敞口与资源分配之间做出取舍。这一层级需要清晰的业务目标、最高层级的处置授权与真实的经营问责机制。由于决策目标本身往往充满博弈与冲突,在可预见的周期内,负责人层级依然由人类决策者牢牢掌控。
对比 2025 年与 2026 年的主流企业软件可以发现,现有巨头正在集体沿着这一阶梯向上攀爬:

一年前,大多数企业软件内嵌的 AI 产品还徘徊在“检索助手”阶段,本质上只是挂载在数据库上的问答工具。而如今,Docusign(合同红线审核)、Procore(施工合同与变更单审查)、Salesforce(专业化销售与报价智能体)、ServiceNow(故障预案与受控执行)等产品已普遍跨越到“流程智能体”与“早期策略智能体”层级。
然而,巨头向上延伸的势头虽然凶猛,却存在一个致命的结构性天花板:它们的判断力边界,被牢牢锁死在自己所掌管的那一套局部数据底座之内。
单据不等于任务:为什么巨头的局部数据底座吞不下完整业务?
巨头可以在自己的核心记录周围实现越来越多的自动化,但客户真正需要解决的问题,天然远大于任何单张系统记录。
软件巨头的产品构建逻辑,始终是“以自身拥有的数据记录为中心向外展开”。但真实的商业世界不是围绕单一数据库运转的:
| 数据底座单据(巨头的局部视界) | 真实业务任务(客户的端到端目标) | 巨头系统看不见的盲区与外部上下文 |
|---|---|---|
| 合同(Contract) | 法律事务(Legal Matter) | 条款背后的商业妥协、口头合伙人风险评估、非结构化的微信/邮件往来与庭外博弈 |
| 工单(Ticket) | 问题解决(Resolution) | 跨部门与外部供应商联调、客户实际生产环境受阻排查、复杂的系统间依赖与业务恢复验证 |
| 商机(Opportunity) | 成单销售(Sale) | 面对面的信任建立、未经录音的高层私下沟通、跨组织政治博弈与定制化方案的反复拉扯 |
客户真正要完成的工作,本质上远大于系统里的单据记录(The job is bigger than the record)。现有巨头建立的只是一个“局部工作系统(Local System of Work)”。而企业客户面临的真实任务,不仅横跨内部多个孤立的业务系统与职能团队,更频繁穿透企业边界,牵涉买方、供应商、外部法务、审计机构等多方利益主体。不同的参与方持有不同的片段信息,诉求往往互相冲突。
此时有人提出,像 Claude 或 Codex 这样的通用大模型具备跨应用调用的能力,能否直接统管一切?事实并非如此简单。
这正是垂直 AI 能够扎根生长的战略缝隙:不依附于某一家巨头的单点记录,而是立足于解决某一类具体业务的全生命周期,以独立中立的姿态贯穿跨部门、跨系统的完整链条。
从“记住”到“学会”:垂直 AI 怎样靠课程工程造出专业护城河?
能够掌控更完整的工作流程之所以至关重要,是因为它让系统能够观察到产出最终结果的全部“决策路径与纠错过程”。
在特定场景下,一个模型要想表现出专家级的专业水准,必须依赖配套的领域线束(Vertical Harness)——包括精准的上下文注入、专有工具链、业务工作流与严谨评测集。而系统的持续迭代,依赖于每一次任务交付后,由实际业务成果、专家纠错反馈与端到端交付数据共同构成的“学习闭环(Learning Loop)”。
许多企业管理者容易把“通用模型的记忆功能”与“专业系统的学习能力”混为一谈:
| 维度 | 通用模型的全局记忆(Remembering) | 垂直系统的深度学习(Learning) |
|---|---|---|
| 核心机制 | 跨会话召回用户的历史偏好与零散事实 | 掌握特定领域的专业质量标准与机构内隐规则 |
| 输入来源 | 用户过往对话、历史提示词与零碎操作记录 | 合成专业课程、严密评测集(Evals)与生产环境纠错 |
| 掌握层次 | 表层上下文关联(“客户上周提过喜欢简洁格式”) | 深层因果理解(“为何合伙人必须删除第 7 条责任豁免款”) |
| 持续迭代 | 单纯增加上下文长度,无法从错误中提升判断力 | 通过专家纠错与交付结果,形成自强化的学习闭环 |
学习是对专业标准与质量因果的真正掌握。它分为两个不同层次:
- 学习专业人士如何做事(Learning the profession):理解该行当顶尖专家的作业规范、思维范式与高质量成果标准。
- 学习特定机构如何做事(Learning the institution):掌握某家具体企业的专属模板、过往判例、内部风险偏好与例外事件升级规则。
要想同时教会智能体“专业标准”与“机构规则”,初创团队并不需要在一开始就坐拥海量的历史客户数据。它们可以通过工程化手段“主动制造专业课程(Manufacture a curriculum)”,随后在真实的生产部署中吸收特定机构的个性化规则。
法律科技独角兽 Harvey 针对其 Tenet 模型的后训练实践,为垂直 AI 跑通这条路径提供了行业范本。Harvey 在启动训练时并没有直接使用客户的私有数据,而是利用合成数据、公开法律判例与合伙人级专家规则,人工制造了约 1,750 个高仿真法律任务环境。每个任务环境都完整模拟了一名资深合伙人交办的真实复杂事务,配套了全套卷宗文档、调用工具与专家评分细则,平均每个任务包含大约 50 项具体的审查与输出指标。
Harvey 的工程化实践展现了这一学习闭环的标准落地流程:
- 环境构建(Environment Setup):制造约 1,750 个高度仿真的法律任务环境,完整复刻合伙人交办的复杂事务;
- 全套卷宗与工具配备(Tool & Context Wiring):为每个任务环境配套完整案件卷宗、证据链条与检索调取工具;
- 专家细则评测(Expert Rubrics):平均为每个任务设定约 50 项具体的审查、合规与逻辑输出量化指标;
- 长周期强化学习(Checkpointed RL):将耗时数小时的复杂长流程拆解为细分检查点,针对中间逻辑推演进行严密打分与迭代。
通过这种“制造课程”的方式,垂直系统绕过了耗费数年缓慢搜集客户历史数据的被动等待,直接以极高的密度训练出模型对特定复杂任务的专业判断力。
对于需要运行数小时乃至数天的“长周期长流程智能体(Long-running Agents)”,这种学习闭环的价值尤为显著。当一个任务包含复杂的长逻辑链条与密集的中间交接时,垂直系统能够将长周期任务拆解为若干细分检查点,在每个检查点对逻辑严密性进行独立评测与强化。相比之下,巨头系统虽然也能从自身软件内的操作中学习,但它们能学到的永远只是自己那一小块拼图——Docusign 只能学到合同签署,Jira 只能学到工单流转,Salesforce 只能学到商机修改。
终局权力图谱:巨头、模型厂与垂直新贵,谁能在哪类战场胜出?
在这场关于未来企业工作权的重构中,三大阵营的角色边界与权力分配已逐步清晰:

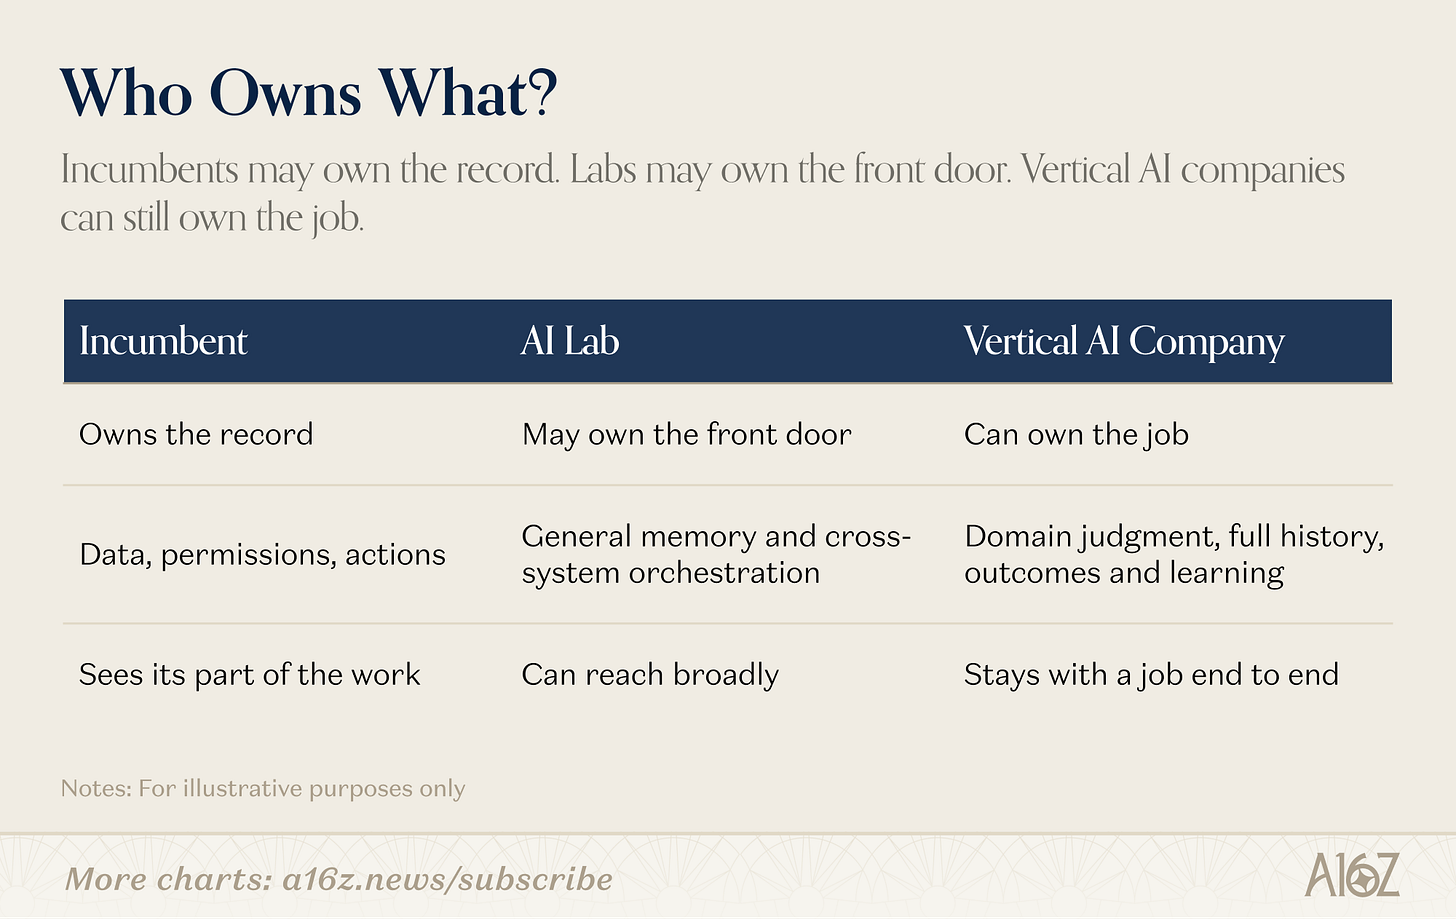
| 阵营 | 核心掌管资产(Who Owns What) | 核心竞争优势 | 固有的结构性短板 |
|---|---|---|---|
| 现有巨头 (Incumbents) | 核心业务数据底座(CRM/ERP等)、组织架构权限与既有 API | 客户基数庞大、历史数据沉淀深厚、切换成本极高 | 视野锁死在局部记录内,无法跨越组织与多系统边界 |
| 模型厂商 (AI Labs) | 统一交互前门、基础大模型能力、全局记忆中枢与跨应用编排 | 研发资源雄厚、跨生态触达能力强、泛化推理通用 | 缺乏垂直行业专业纵深,无法对具体业务结果承担交付责任 |
| 垂直 AI (Vertical AI) | 垂直领域专业判断力、全生命周期业务数据、交付责任与闭环飞轮 | 极致专注于特定复杂工作,端到端解决问题,自主制造专业课程 | 需要深入行业构建专家信任,冷启动阶段依赖精细化工程构建 |
并非所有垂直领域都适合诞生独立的纵向 AI 公司。a16z 提出了四项评估垂直 AI 赛道可行性的黄金准则:
- 纠错与反馈的高效性(Efficient Expert Feedback):领域内的资深专家能否在短时间内迅速指出 AI 产出的对错,并给出明确、可量化的改进建议?
- 任务对专业判断的依赖度(High Judgment Density):该项工作是否具备足够的智力复杂度,需要依赖主观经验与策略权衡(Judgment),而非写死几行 if-else 规则就能解决?
- 业务发生的高频性(High Frequency of Occurrence):该项工作在企业日常运营中是否频繁发生,能否为模型提供源源不断的真实训练与迭代样本?
- 能否从单点切入并拓展为整项工作(Wedge to Full Workflow):能否先接管某一个具体子任务(例如起草缺陷调查报告),随后在实际交付中逐步渗透,最终演进为负责整项复杂任务的端到端解决?
在法律、税务、会计以及复杂的工业制造场景中,这些准则得到了充分印证。例如在制造工厂出现部件缺陷时,质量工程师必须调取测试结果、供应商单据、设备历史日志并对照工厂规程,最终给出整改决断。缺陷报告可能存在于某家巨头的系统里,但没有任何单一软件能统管全流程。垂直 AI 可以从撰写调查报告切入,逐步演变为端到端的质量责任系统。
在简单的单据归档与基础流程场景中,既有的业务数据底座配合一个通用模型前端确实足以应付。但在那些高频发生、深度依赖专家裁决、且拥有强学习闭环的核心业务战场上,垂直 AI 原生团队依然拥有巨大的战略纵深。现有巨头或许拥有数据底座,模型厂商或许控制交互前门,但真正精通并最终交付工作本身的,依然属于专注深耕的垂直创造者。
The Incumbents Are Coming

The bullish case for incumbent systems of record is that AI makes systems of record get more important, not less. Why? Because in theory the customer can now pipe the system’s data into Claude or Codex and skip the AI-native app.
As agents do more work through these systems, the data and actions they control become more valuable. An incumbent system of record plus a general agent (or an agent built by the incumbent) therefore might be enough to get the work done. This is what Salesforce just announced in partnership with Anthropic: Claudeforce lets you work with the Salesforce CRM from inside Claude without having to open Salesforce (or so they claim!).
The argument is partly correct. The incumbents aren’t sitting idly.
The incumbents have an incentive to control and charge for access to their data, and now to push their own agents forward too. We’re already seeing incumbents market products that move from simply storing information toward doing more of the work itself. Docusign’s Iris reviews contracts, Atlassian’s Rovo aims to resolve and route requests, and Klaviyo’s Composer builds campaigns and assesses marketing performance. These products move incumbents beyond the “slap on a chatbot” strategy and into taking action.
At the same time, Claude is starting to coordinate work across applications, making it possible for general-purpose agents to act as a layer above the incumbents. Claudeforce shows what that can look like: Claude can become the front door to the job while Salesforce still controls the underlying CRM data and actions. The interface and the system of record look like they’re unbundling, creating an opening for AI-native startups to rebundle around the job.
So where can startups still compete?
The vertical AI-native company has to win through focus. It has to perform a specific cross-system job better than an incumbent’s purpose-built agent or a general-purpose agent like Claude, which will be able to reconstruct it from the underlying tools. Focus can earn the vertical startup deeper access, a deliberate data asset, more specific context, and a learning loop that builds a better understanding over time of what good work looks like for a given job.
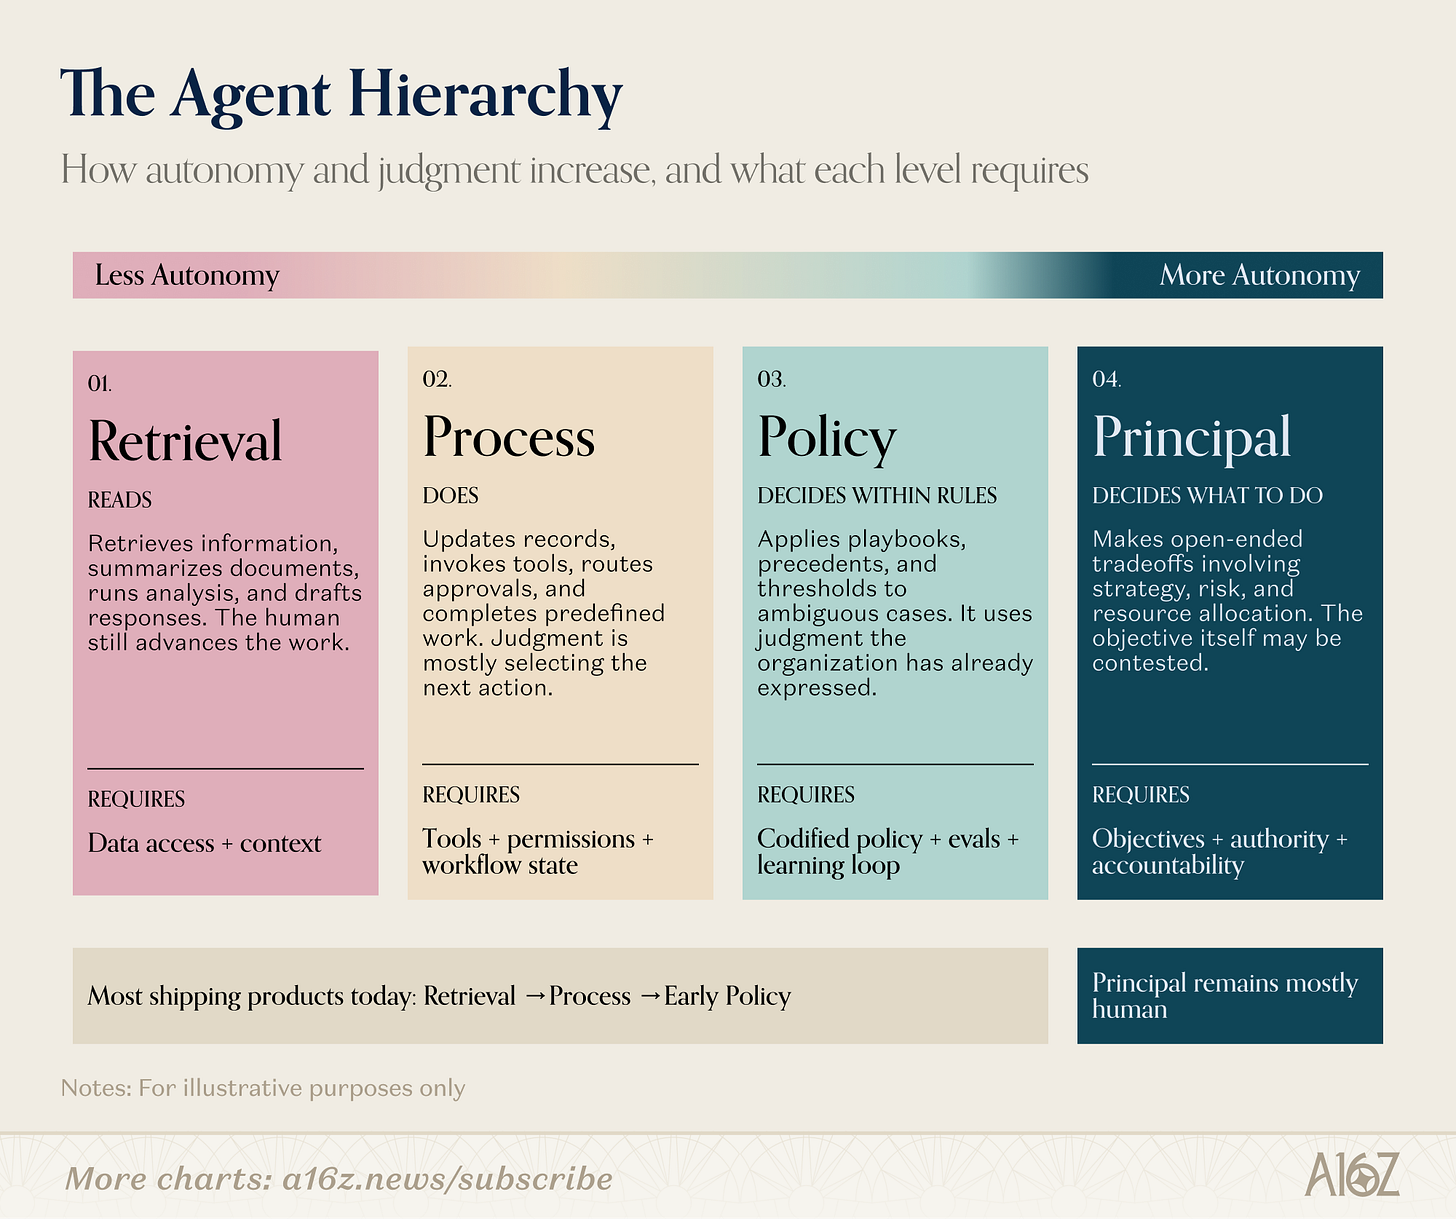
To see where incumbents are strongest and where vertical AI companies may have an advantage, it’s helpful to think about the four types of application-level agents, distinguished by how much autonomy and judgment each requires.
Retrieval assistants find information, summarize documents, answer questions, and draft responses. Process agents carry out rule-based work like updating records or routing approvals, using limited judgment to interpret the task, and act. Policy agents apply the rules in an organization’s playbooks, precedents, and thresholds to ambiguous cases. Principal agents make judgment calls about what the organization should do, often with open-ended tradeoffs around strategy, risk, and resources.
A year ago, most incumbents’ AI products were still at the retrieval stage, if that. They functioned mostly as chatbots and analytical tools pulling from existing records. Now, more can take action based on the workflows, permissions, and rules already embedded in their products. A few are beginning to apply narrow, human-defined policy. Judgment gets harder when the decision depends on information outside the record that the incumbent manages.
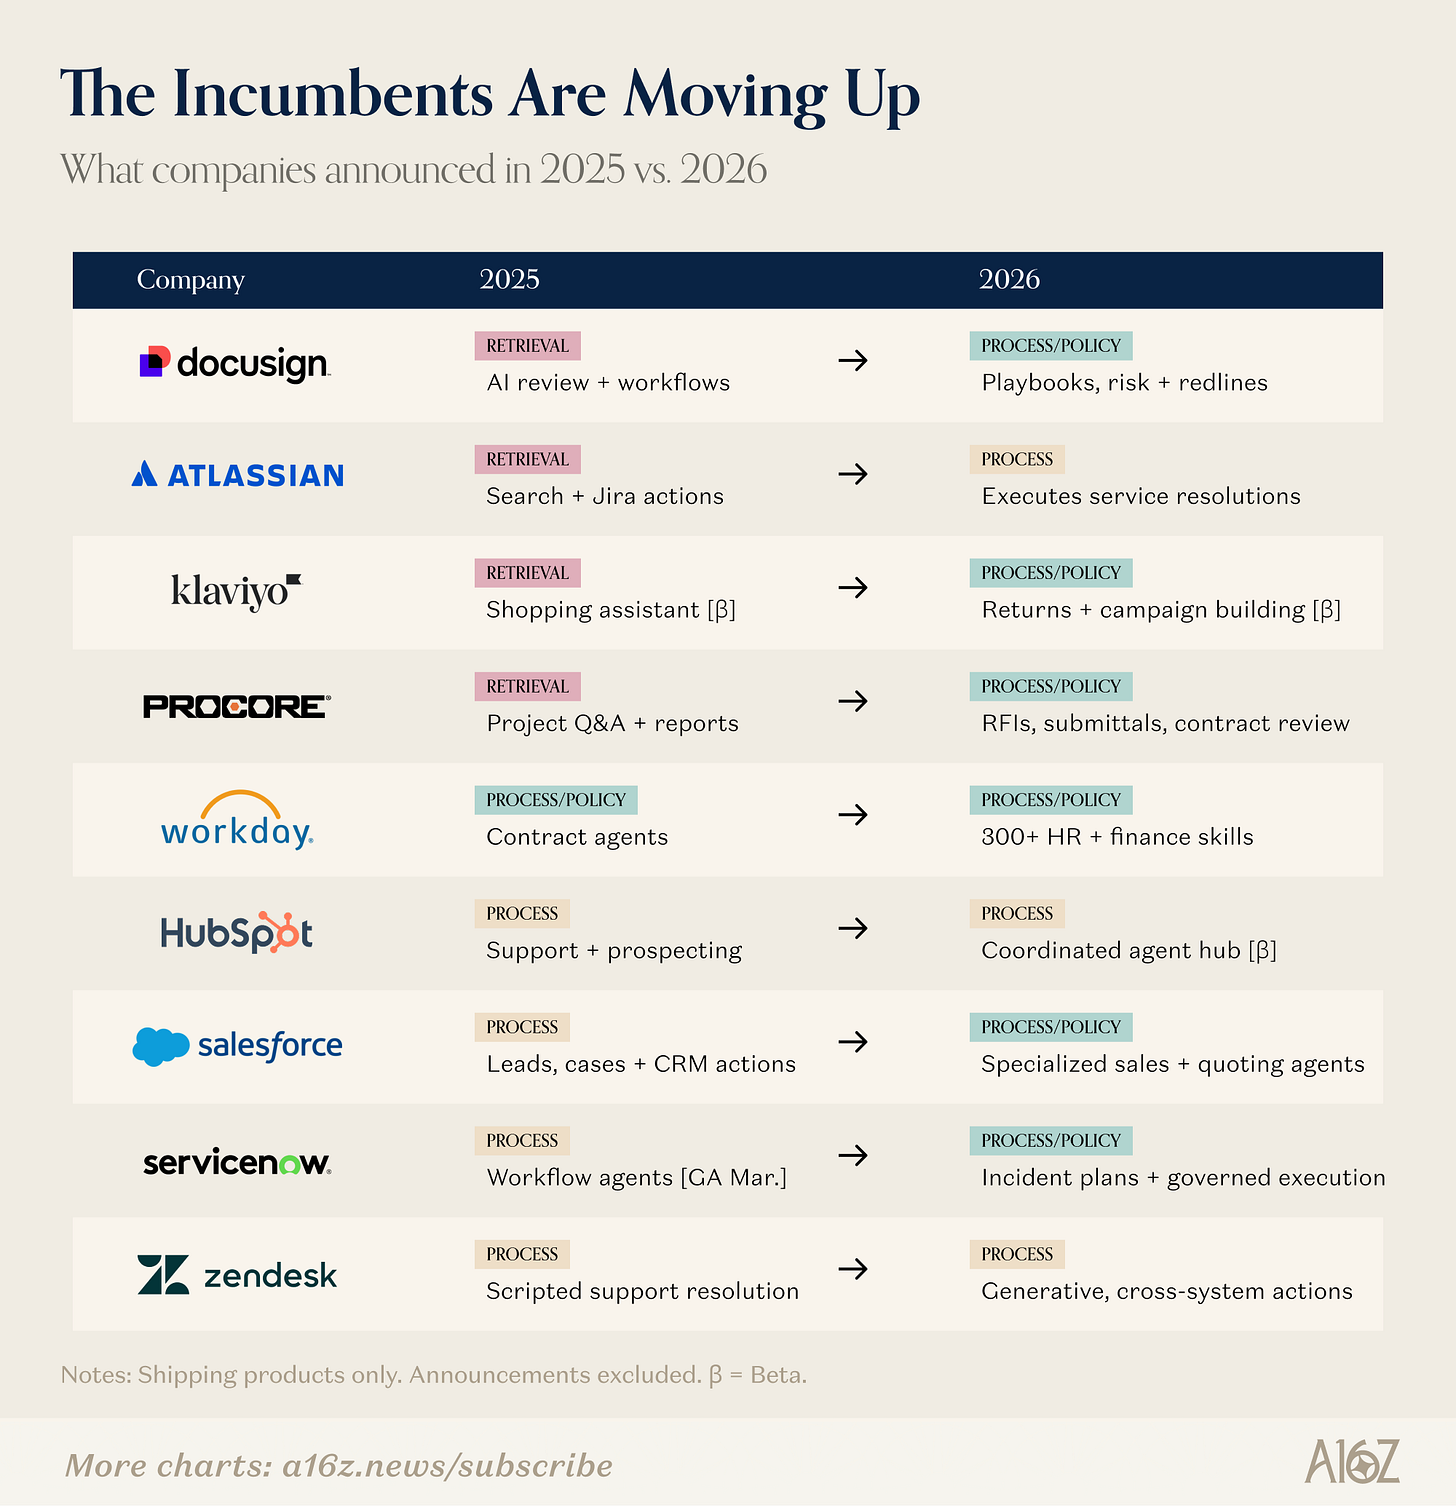
The broad shift we’re seeing is incumbents moving up the hierarchy, from retrieval and process toward more judgment through policy, like Docusign’s Iris applying a legal team’s playbook. But that judgment is still largely bounded by the record the incumbent owns.
An incumbent can automate more of the work around its core record, but the customer’s job to be done is bigger than the record. This isn’t a hard technical boundary because incumbents can pull in outside data and add workflows, but their work still expands outward from the record they already own.
A customer’s work gets done through a combination of its people, processes and software. The contract is not the legal matter, the ticket is not the customer’s resolution, and the opportunity is not the sale. The full job crosses applications, teams, and even companies. Different parties may hold different information, and want different outcomes. The incumbent is limited to building a “local system of work” but the larger opportunity is to manage the job across boundaries, including all of the parties, the people, the documents, decisions, revisions, and the final result.
A general purpose agent like Claude or Codex may be able to reach across all these systems, but access alone doesn’t mean it can perform the job well. Even using MCP, pulling info across applications has latency, and each application may describe the same customer, contract, or transaction differently. Even if a general purpose agent can access every app in one company, it doesn’t automatically have access to information held by external parties (e.g. between buyers and suppliers).
Even with these limitations, Claude can still sit above systems of record. Claudeforce makes Claude the front door to the job while Salesforce still owns the CRM data and actions. And Claude can keep gaining context through deeper integrations blessed by the incumbents.
Owning more of the job matters because it lets startups see the decisions and corrections that produced the final result. A model performs better on a specific job via a vertical harness with the right context, tools, workflows and evals. The learning loop is what improves the system - the model + harness - after each job, using the agent’s work, expert feedback, and outcomes themselves to improve the next attempt.
Completed records alone don’t automatically suffice as a training curriculum for the work. A signed contract shows what the parties agreed to, but not every alternative considered or every reason for an exception. A closed ticket shows the resolution, but not every hypothesis the support team tested.
The labs are also building general-purpose memory, so preserving context alone is not a durable advantage. Remembering and learning are different. Memory can help a general purpose agent recall a customer’s preferences or a decision made last week. But it doesn’t tell the agent whether the work was good or why an expert changed it or what to change next time. Focus lets the company see more examples of the same job, learn faster, and get better at measuring improvement.
There are two kinds of learning. Learning how a good professional does the work. A company can begin teaching that with assignments created by experts, realistic examples, and standards for a good result.
Learning how a particular firm or customer does the work, including its templates and precedents, risk thresholds and escalation rules. That can begin with the customer’s existing materials and improve through corrections and exceptions in the training process. Some lessons about the profession can improve the product for every customer, but lessons about one firm may just improve the product only for that firm.
To learn both the profession and the institution, the startup doesn’t need to start with the largest stock of historical data. It can manufacture a curriculum for the profession, then use production to learn the institution. As open-weight models and post-training increase, assembling the right data and evals becomes even more important.
Long running agents especially benefit from learning loops. When an agent does work over hours or days, through a complex logic chain with many intermediate decisions and handoffs, the quality of the learning loop matters even more. The longer horizon task can be unbundled and evaluated through a set of checkpoints.
To be clear, incumbents will also learn from the work performed inside their products. But that learning will cover only their part of the job: the contract review inside Docusign, the ticket resolution inside Jira, or the pipeline update inside Salesforce.
Harvey’s work on Tenet shows what the path for vertical AI can look like. Harvey post-trained an open-weight model using synthetic data, public legal data, and human-expert created data, without using customer data to start. It created roughly 1,750 legal-task environments, each simulating a partner-assigned matter, complete with documents and tools and an expert rubric for a high-quality result. The average assignment had about 50 specific criteria. Instead of waiting years to accumulate enough customer history, Harvey manufactured a curriculum it could use to train and evaluate its model.
Harvey’s broader work also shows how a vertical company can train a model for different parts of the job, including industry-specific capabilities like M&A diligence and understanding a firm’s total knowledge.
The startup’s opportunity is to put it all together. Vertical specificity helps the startup to break the work into specific capabilities, tackle the practical frictions around data rights, systems, and permissioning, and fits the product into the customer’s daily work. Eventually, it can feel comfortable taking responsibility for the result. Deployment and responsibility are key here!
Using Harvey as one example, here are a few axes for evaluating potential vertical AI markets.
- Can an expert quickly tell what the AI got right or wrong, and explain how to improve it?
- Is the work hard enough that judgment matters (vs. simple rules)?
- Does the work happen often enough for the product to learn?
- Can the startup begin with one assignment and grow into doing an entire job?
The best vertical AI markets tend to meet all four, giving them a strong learning loop.
Many workflows in legal, tax, and accounting meet this test because the work repeats, requires judgment, and experts already review the results. This pattern also shows up in less obvious markets like industrial work. When a manufacturing defect appears, a quality engineer has to gather test results, supplier documents, equipment logs, and the plant rules, then decide what’s acceptable and what needs to change. That information may sit across several systems. One incumbent may store the defect report, but no single product owns the full investigation. A startup could begin with one piece of this work (e.g. drafting the investigation report) and over time own the end-to-end resolution. To do this, it would need to learn both how a good quality engineer investigates a problem and how a particular plant or customer or auditor does it well.
There are jobs where a system of record plus a general-purpose agent will be enough, but there’s still meaningful opportunity for vertical AI-native startups! The strongest vertical opportunities exist where the work happens often, expert judgment matters, and the learning loop is strong. The incumbent may own the record and the lab may control the front door, but the vertical AI company can still win by becoming the best at doing the job itself.

This newsletter is provided for informational purposes only, and should not be relied upon as legal, business, investment, or tax advice. Furthermore, this content is not investment advice, nor is it intended for use by any investors or prospective investors in any a16z funds. This newsletter may link to other websites or contain other information obtained from third-party sources - a16z has not independently verified nor makes any representations about the current or enduring accuracy of such information. If this content includes third-party advertisements, a16z has not reviewed such advertisements and does not endorse any advertising content or related companies contained therein. Any investments or portfolio companies mentioned, referred to, or described are not representative of all investments in vehicles managed by a16z; visit https://a16z.com/investment-list/ for a full list of investments. Other important information can be found at a16z.com/disclosures. You’re receiving this newsletter since you opted in earlier; if you would like to opt out of future newsletters you may unsubscribe immediately.